Build Smarter.
Ship Faster.AI Agent DevelopmentAI Agent DevelopmentMulti-Agent AI & SwarmsAdvanced Hybrid RAG EnginesLLM Cost OptimizationLegacy .NET ModernizationEnterprise SaaS Engineering
Deep technical content on agentic AI systems, LLM cost optimization, Commander Architecture, and production SaaS engineering — from 18+ years of building.
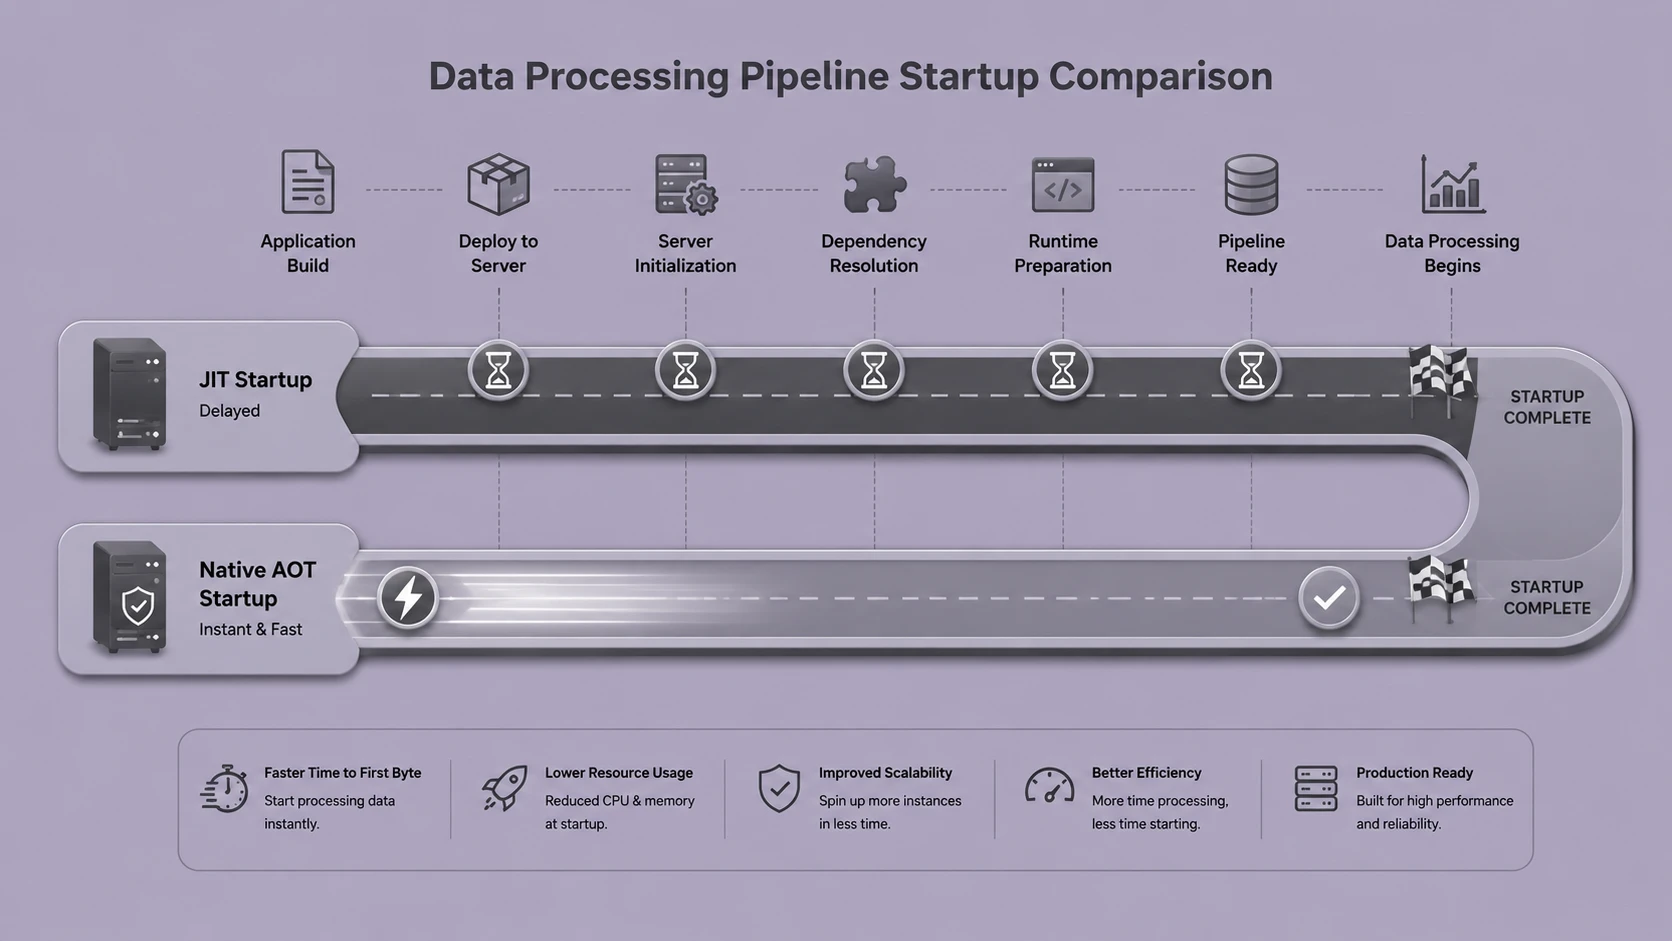
Native AOT in .NET 10: Reducing Server Cold Starts and Memory Footprint for AI Gateways
Learn how Native AOT in .NET 10 improves AI gateway performance by minimizing cold starts, reducing memory consumption, and accelerating cloud-native deployments.
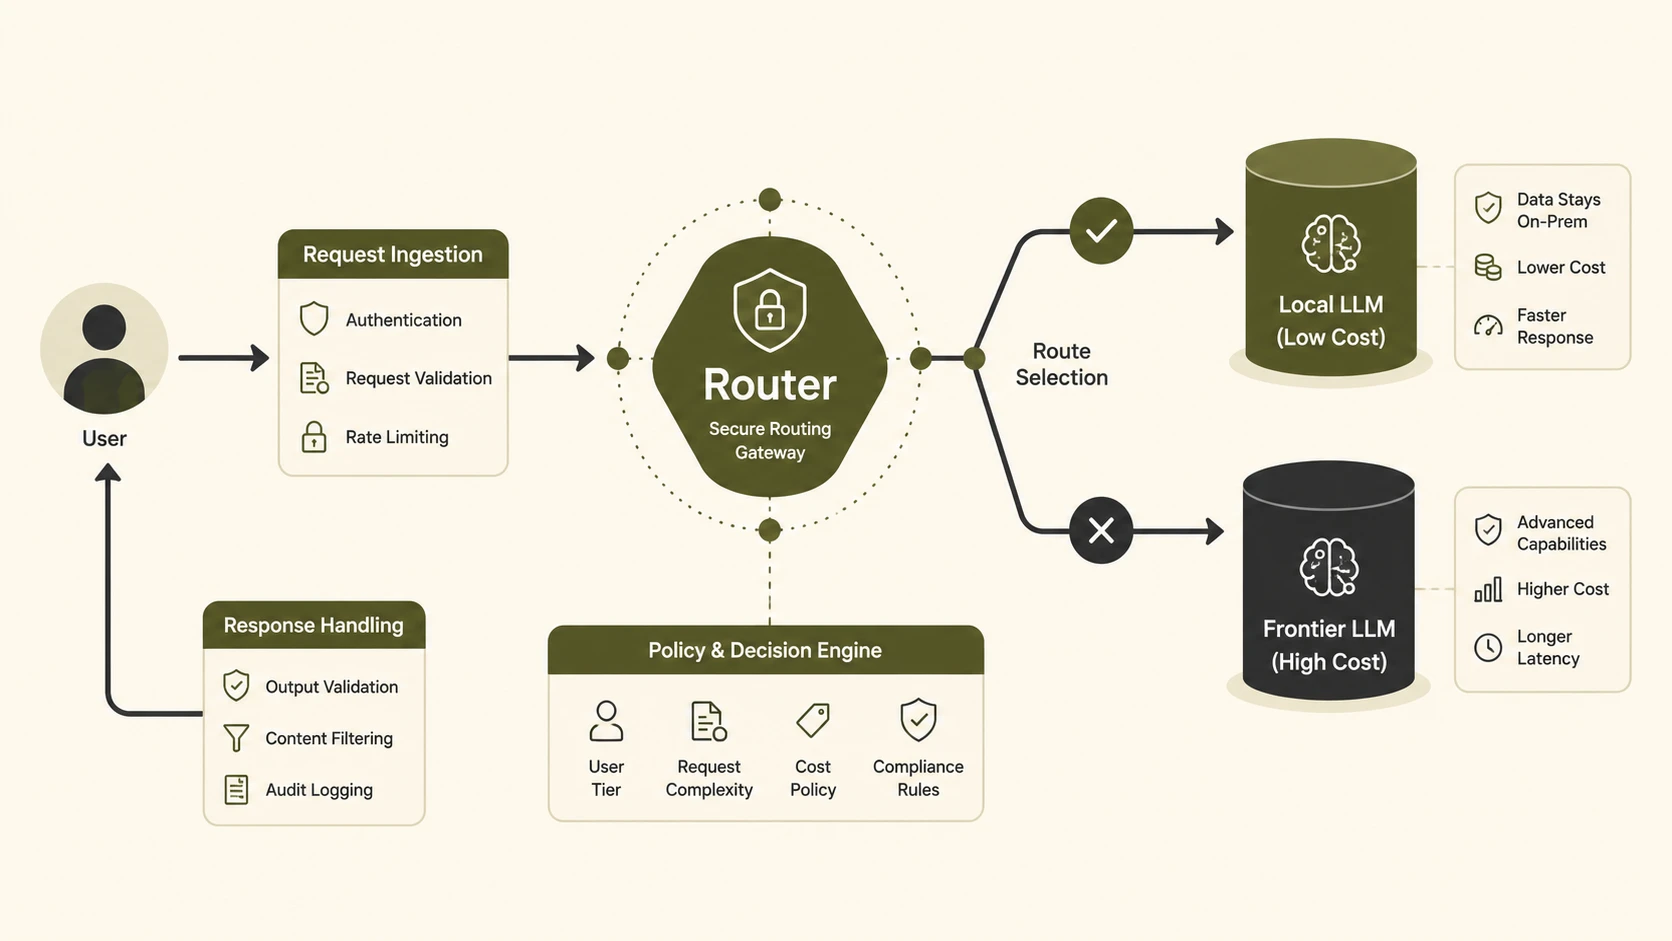
Cost-Optimized LLM Routing: Intelligently Dispatching Tasks Between Local and Cloud Models
26 Mar 2026
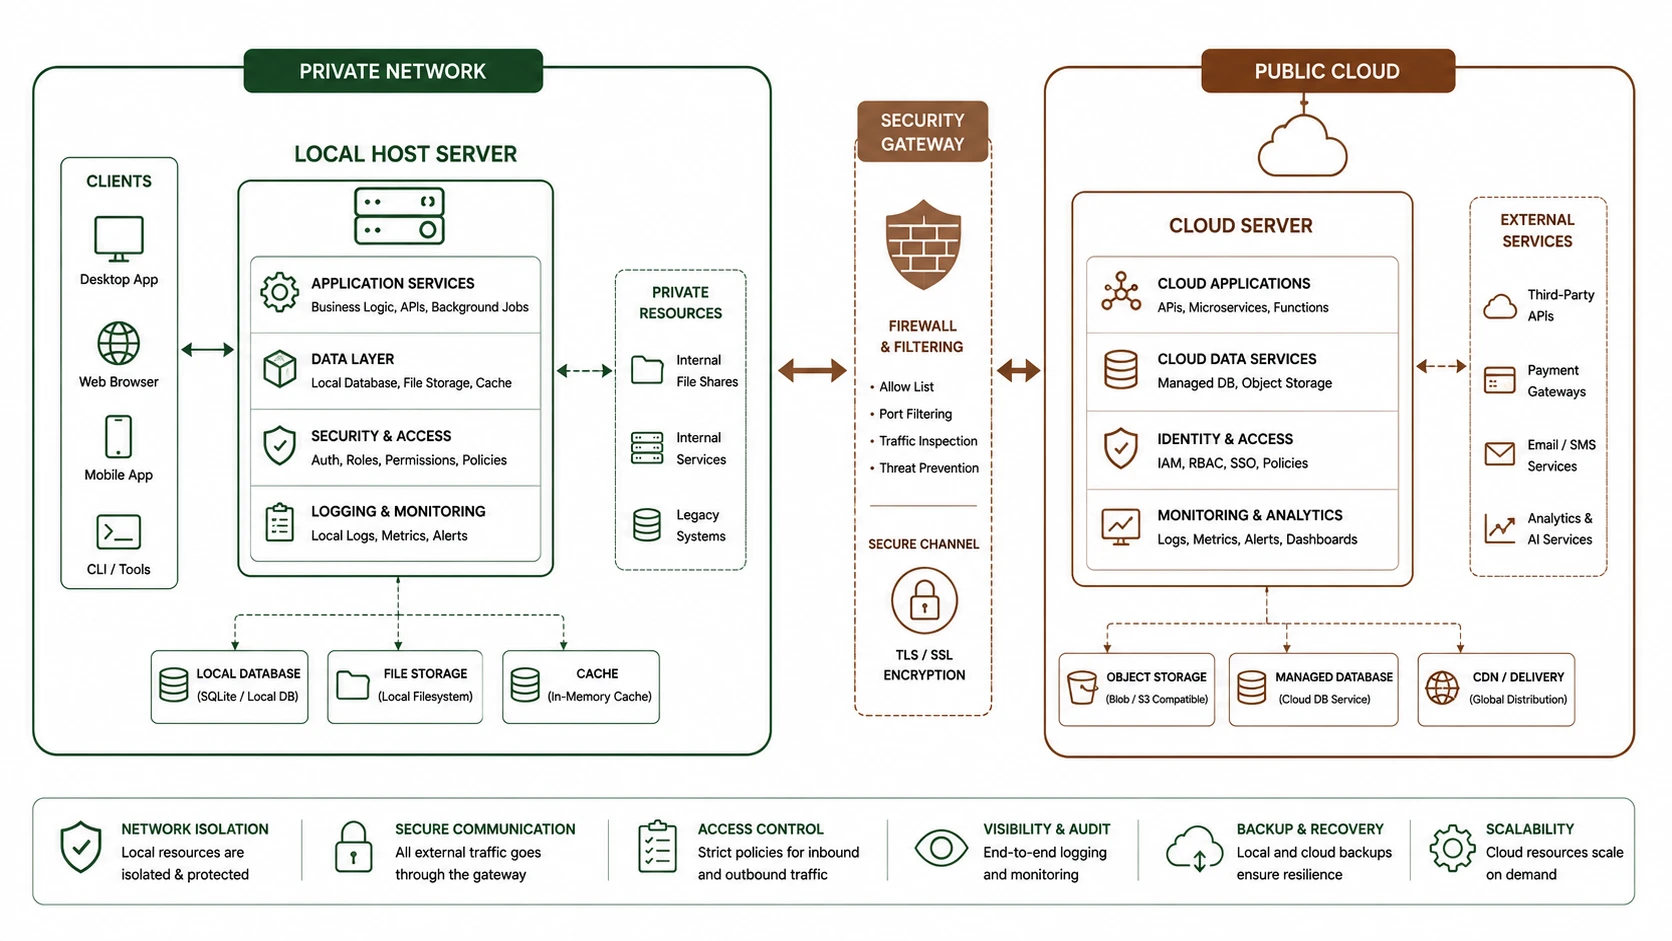
Ollama in Production: Deploying Quantized LLMs Locally to Mitigate Cloud Vulnerabilities
12 Feb 2026
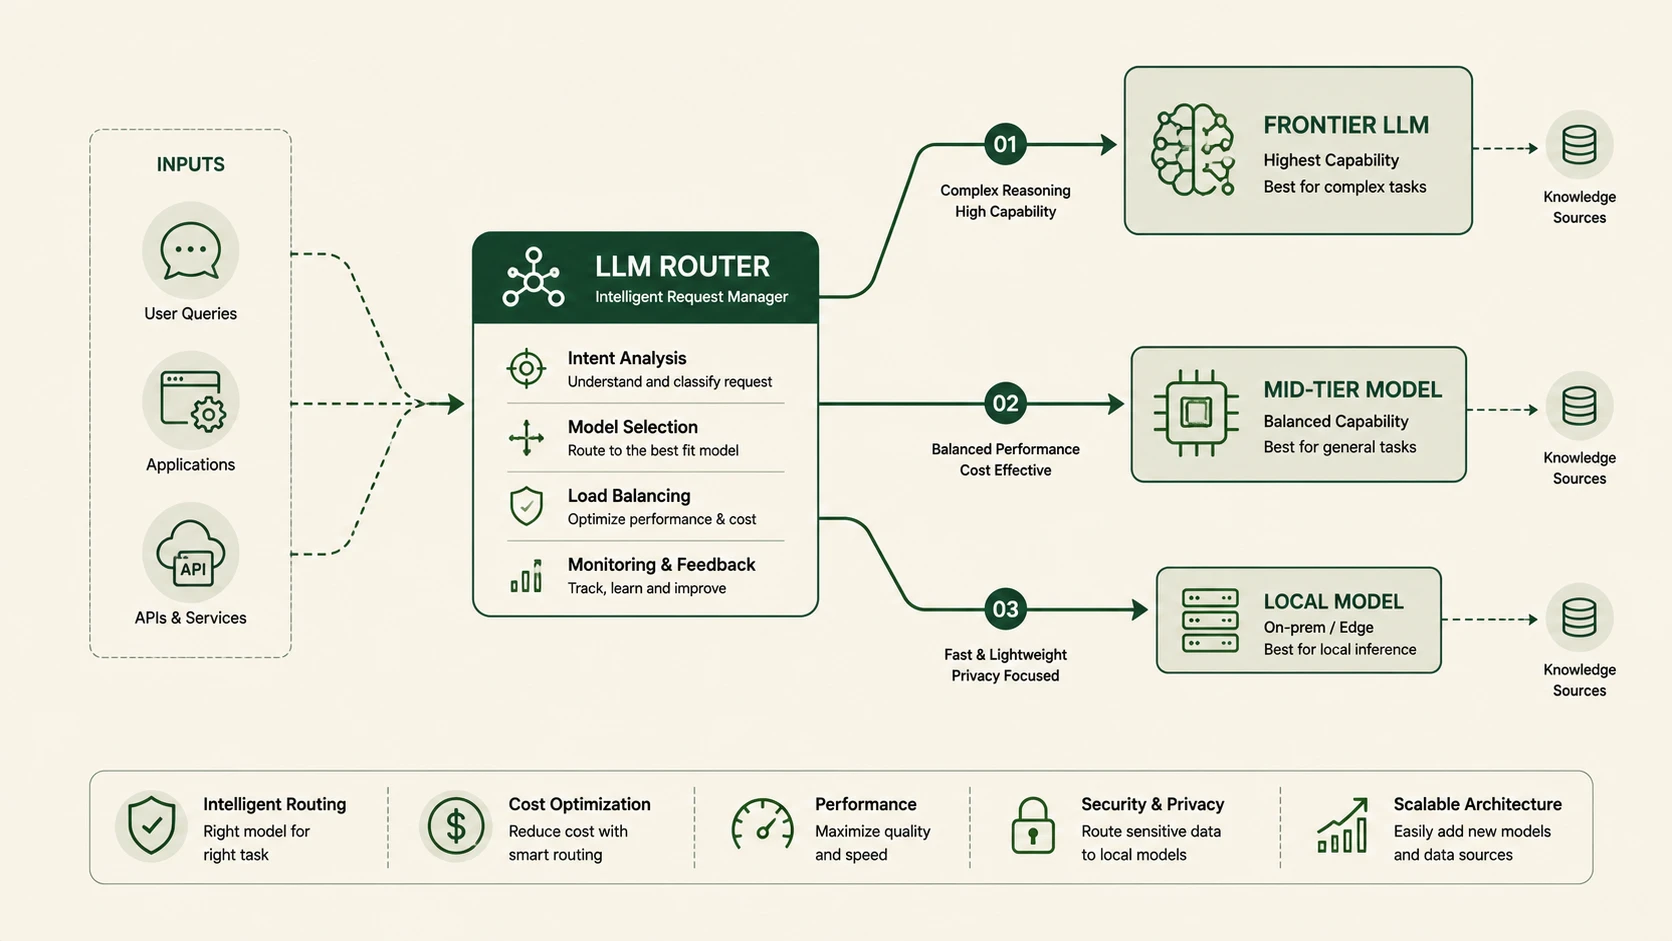
Multi-LLM Orchestration: Managing Asymmetric Model Networks in Production Pipelines
22 Jan 2026
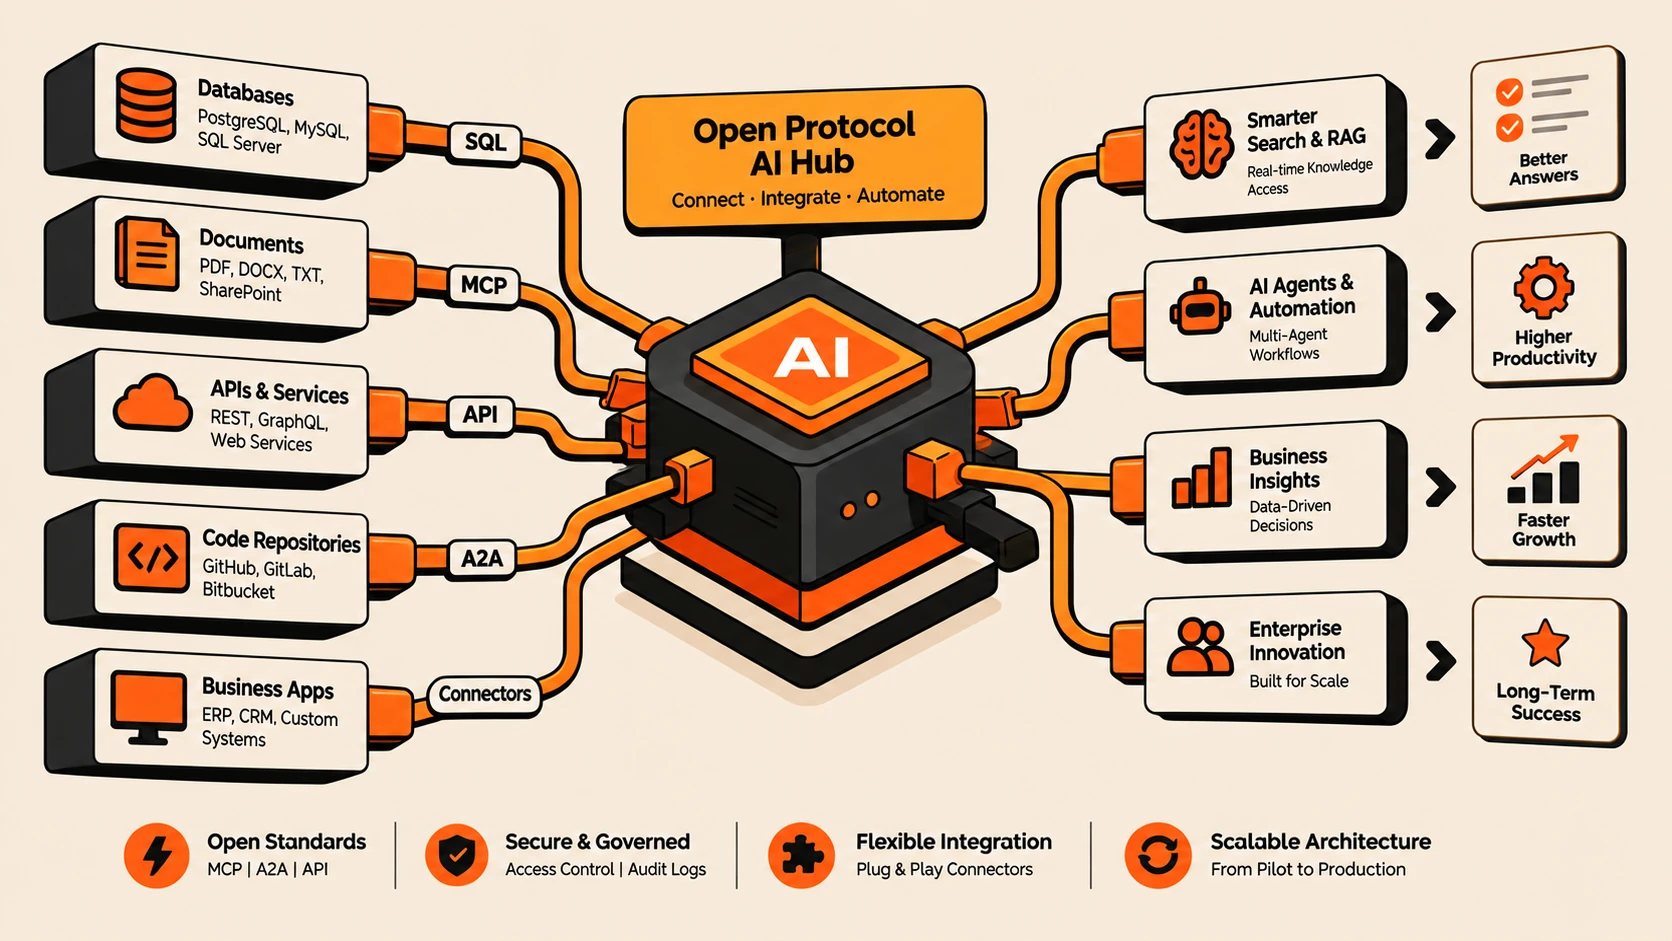
MCP Protocol Explained: Building the Agent Internet with Model Context Protocol
As enterprises move from isolated AI assistants to agentic systems, interoperability is becoming a critical challenge. Model Context Protocol (MCP) provides a standardized approach for connecting AI models with tools, data sources, enterprise applications, and other agents. This guide explains MCP architecture, enterprise adoption patterns, security considerations, and its role in building the emerging Agent Internet in 2026.
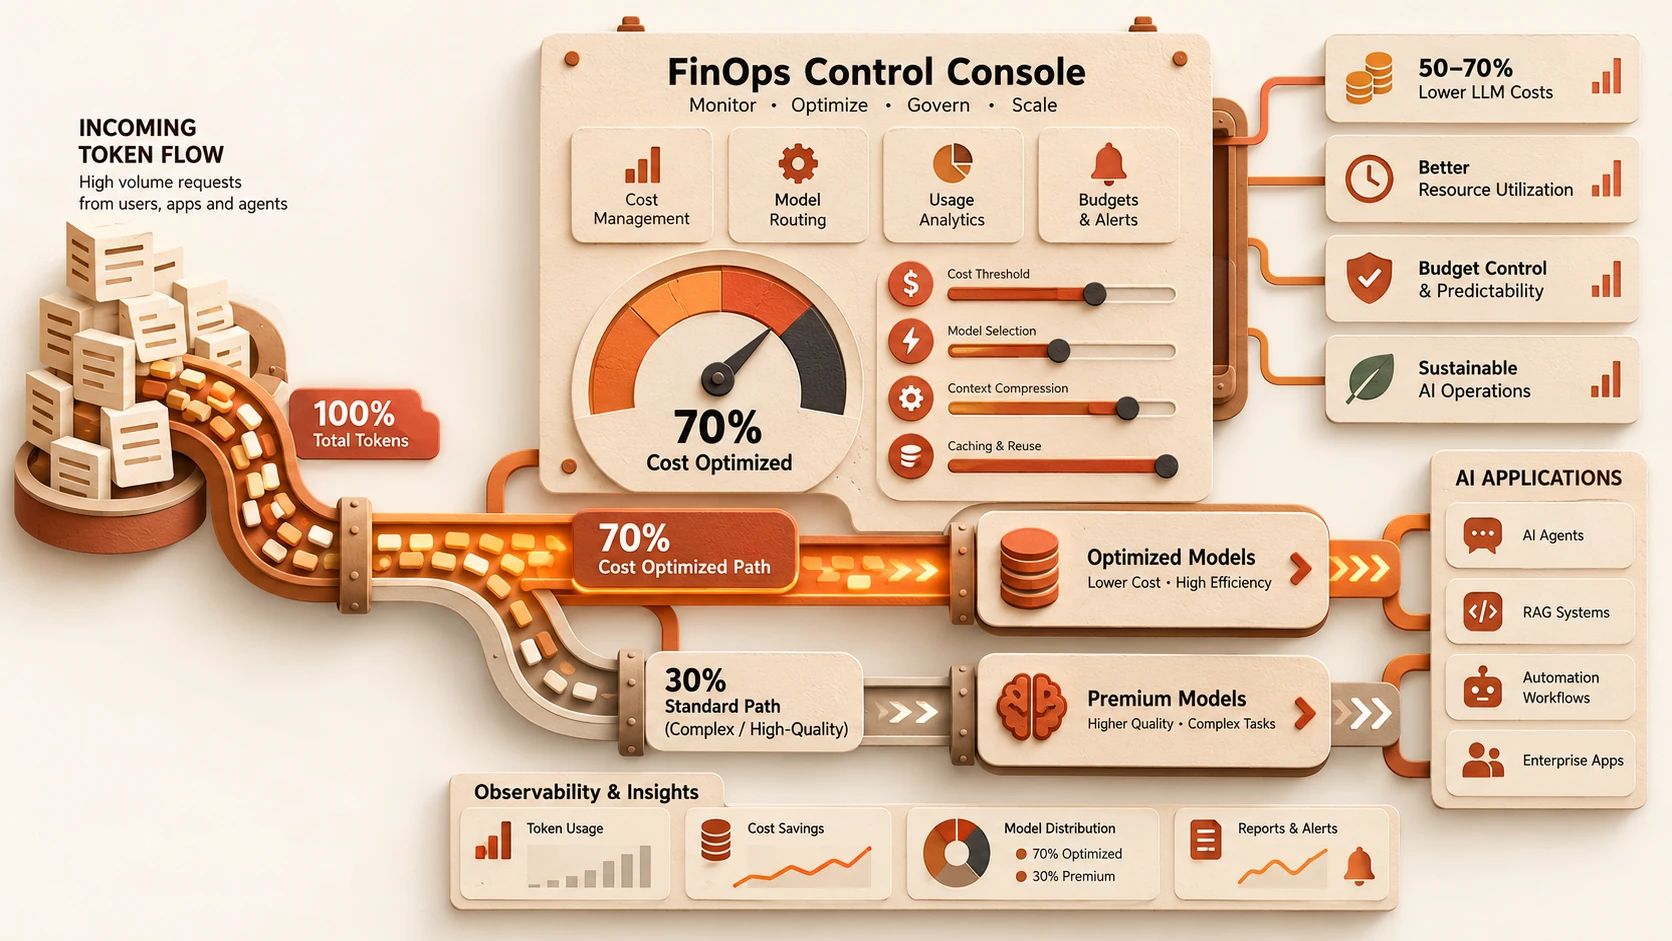
FinOps for AI: How We Cut LLM Costs by 70% Using Hybrid Routing
As enterprise AI adoption accelerates, inference spending is becoming a significant operational expense. This guide explains how a hybrid routing architecture can reduce LLM costs by up to 70% by matching workloads to the appropriate model, implementing governance controls, and applying FinOps principles to AI platforms.
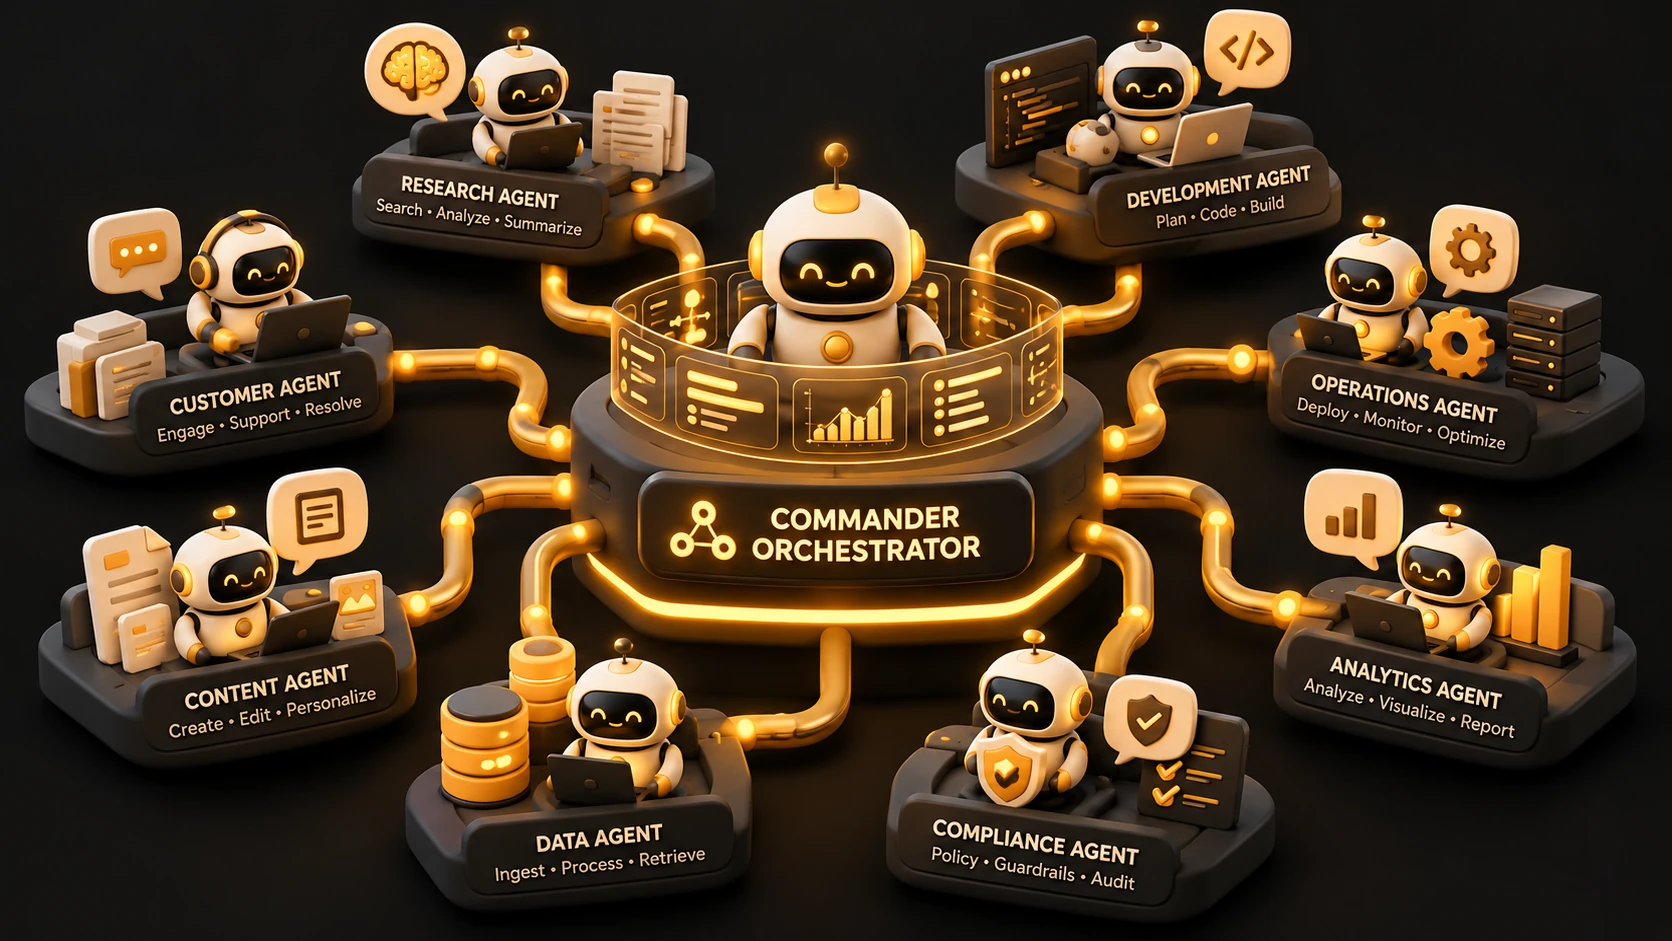
Multi-Agent Orchestration: The Microservices Moment for AI (2026 Guide)
Multi-agent orchestration is emerging as a foundational architectural pattern for enterprise AI systems. This guide explains how organizations are coordinating specialized AI agents, applying orchestration principles similar to microservices, and building scalable, secure, and governable AI platforms in 2026.
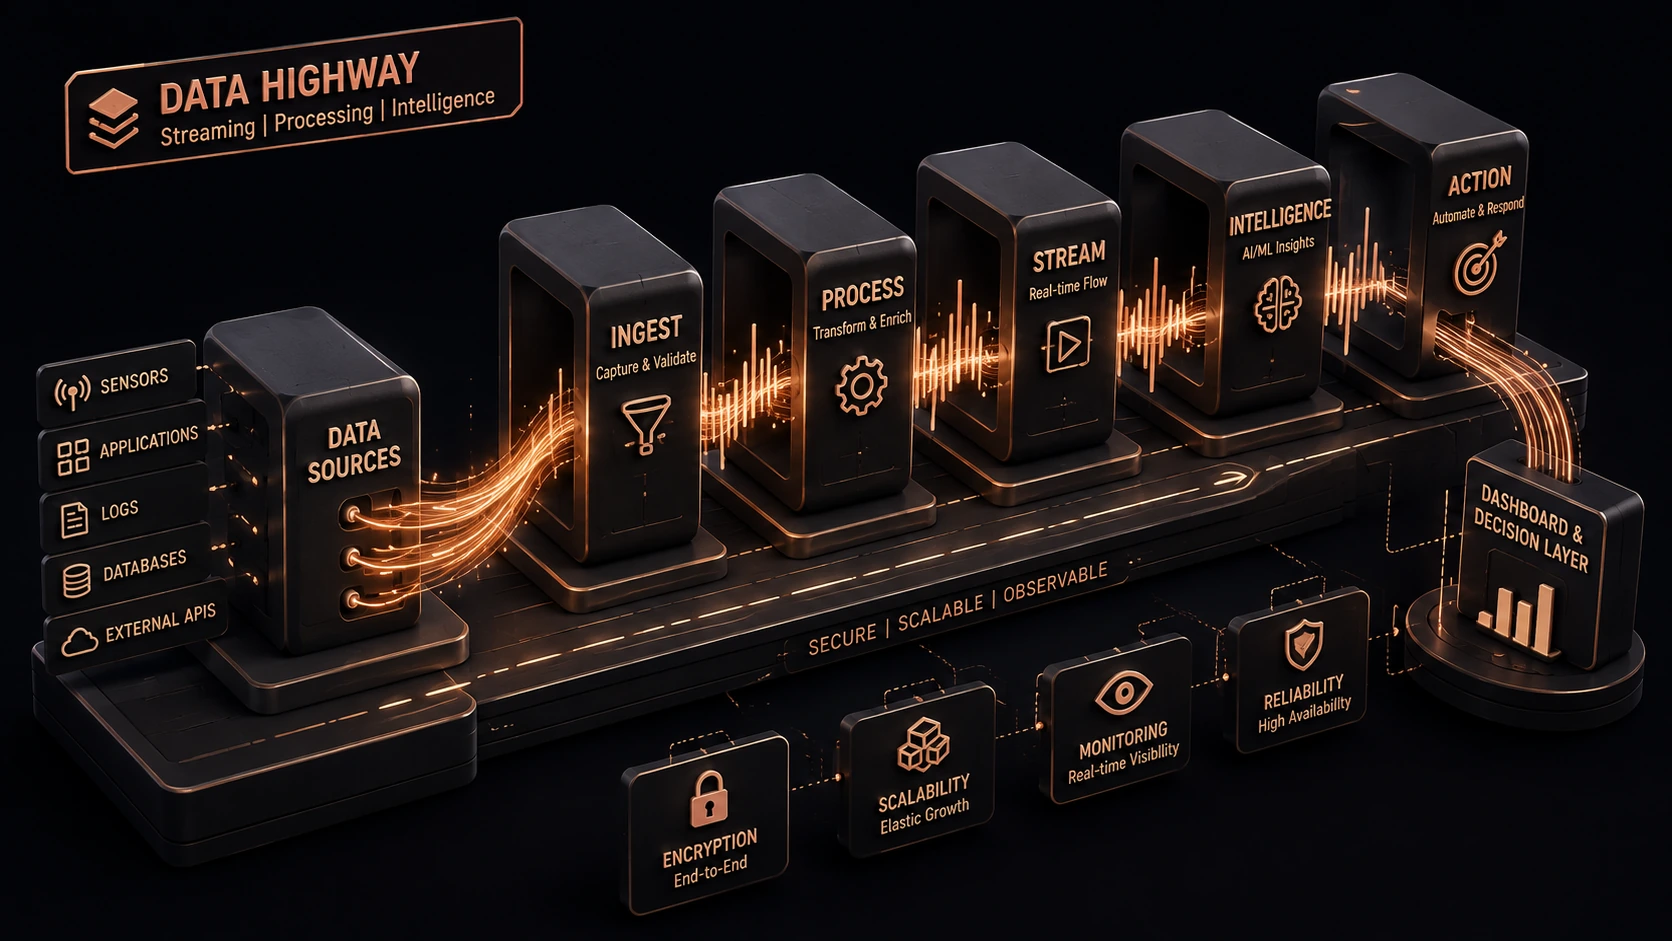
Voice AI Agents in 2026: Beyond Chatbots to Bidirectional Conversational Systems
Voice AI transforms traditional IVR systems into intelligent conversational agents that can listen, reason, execute workflows, and respond in real time. Using speech recognition, large language models, retrieval, memory, and speech synthesis, Voice AI powers customer service, sales, healthcare, and enterprise automation. This guide covers architecture, security, orchestration, latency, deployment, and production best practices.

The CIO's Guide to AI Agent Governance
A CIO's guide to establishing robust AI Agent Governance. Learn about audit trails, human-in-the-loop (HITL) systems, and compliance strategies for secure enterprise AI adoption.

Modernize Legacy .NET Applications with Agentic AI: Zero-Rewrite
Unlock the power of Agentic AI to modernize legacy .NET applications without a full rewrite. Learn architectural patterns, implementation steps, and best practices for enterprise success.

Local LLM Inference with Ollama and Qwen: An Enterprise Deployment Guide
Discover how enterprises can achieve secure, cost-effective Local LLM Inference using Ollama and Qwen. This guide covers architecture, implementation, and best practices.

Semantic Kernel vs LangChain: Which Framework Wins for Enterprise .NET Teams in 2026?
Which LLM orchestration framework should your .NET team choose? Dive deep into Semantic Kernel vs LangChain.NET for enterprise AI development. Discover pros, cons, and real-world trade-offs.

How to Build HIPAA-Compliant AI Agents: A Governance Checklist for Healthcare CTOs
Deploying HIPAA-compliant AI agents in healthcare demands strict governance. This checklist helps CTOs navigate PHI, ensure data privacy, and maintain regulatory compliance.

MCP Protocol Explained: Building the Agent Internet for Enterprise
The Model Context Protocol (MCP) is emerging as a standardized communication protocol that enables AI agents, large language models, and enterprise applications to securely discover, access, and interact with external tools, data sources, APIs, and business systems. Rather than building custom integrations for every AI application, organizations can adopt MCP to create reusable, secure, and interoperable connections across enterprise software. This guide explains MCP architecture, core components, communication flows, security considerations, enterprise deployment models, governance, and implementation best practices for building the next generation of agent-native systems.

How to Reduce OpenAI API Costs by 70% Without Downgrading Your Models
OpenAI API costs can increase rapidly as AI applications scale, but reducing expenses does not necessarily require switching to smaller models. By optimizing prompt engineering, context management, caching, retrieval strategies, request routing, batching, and workflow architecture, organizations can significantly lower API spending while maintaining response quality. This guide explains enterprise-grade cost optimization techniques, architectural patterns, performance trade-offs, and operational best practices for building efficient AI applications.
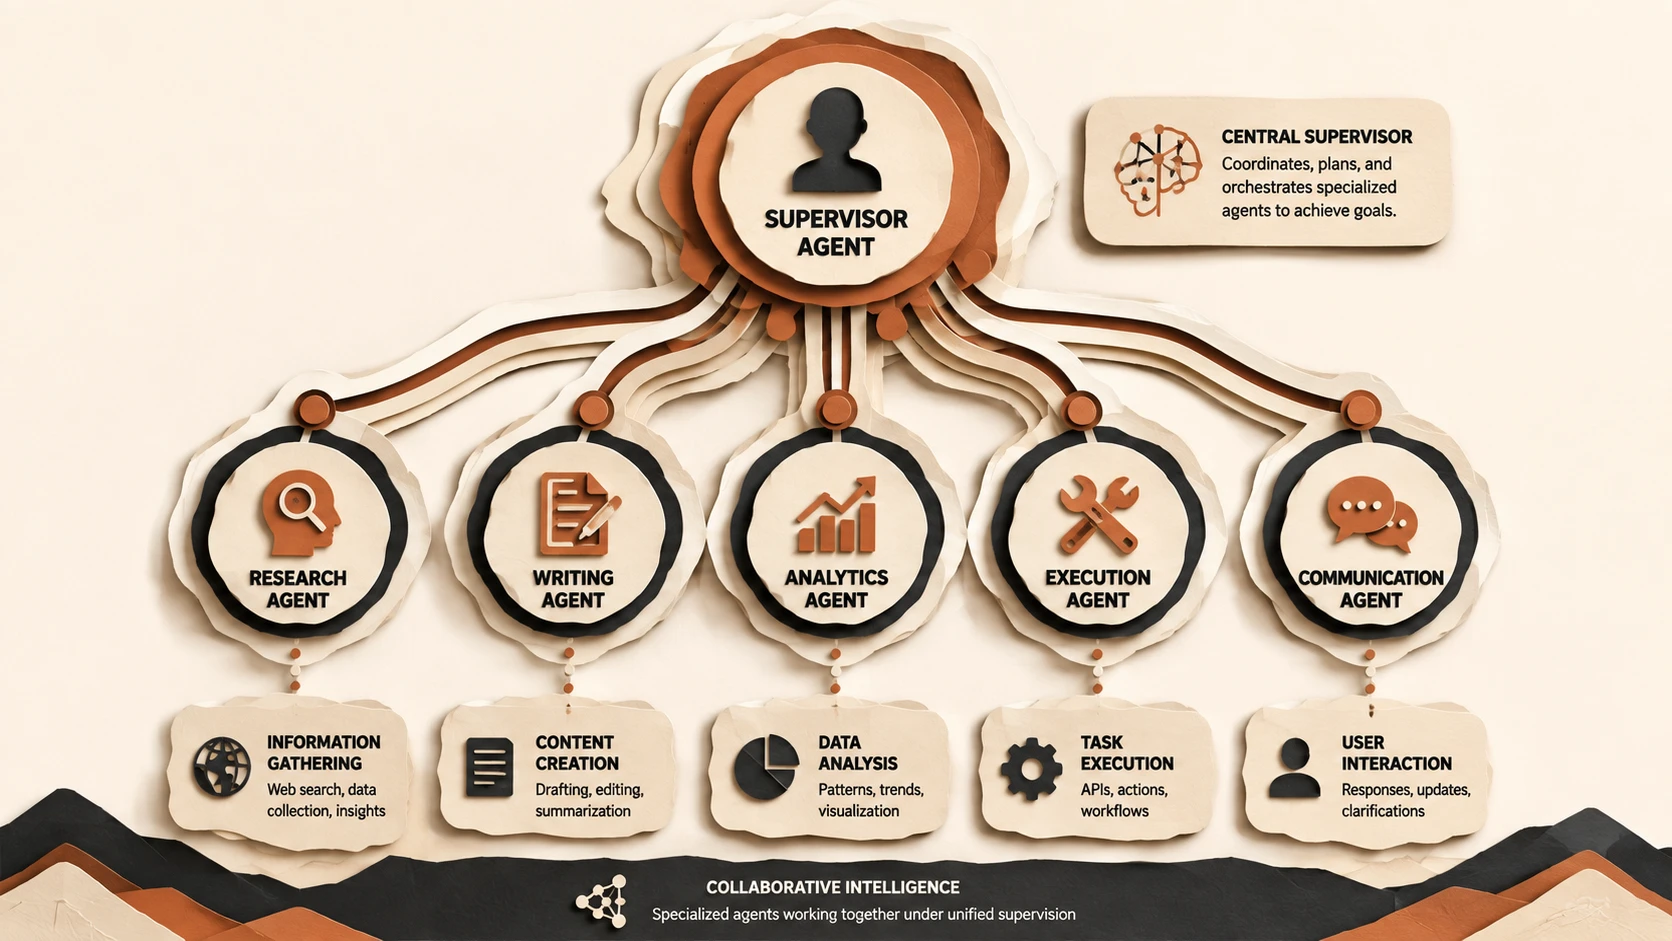
What Is Multi-Agent Orchestration? The Complete 2026 Technical Guide
Multi-agent orchestration is the architectural discipline of coordinating multiple specialized AI agents to work together toward shared business objectives. Rather than relying on a single general-purpose agent, enterprise organizations increasingly deploy teams of autonomous agents responsible for planning, reasoning, collaboration, execution, and governance across business systems. This guide explores orchestration architectures, communication models, planning strategies, coordination patterns, security, observability, scalability, enterprise adoption, and implementation best practices.
Frequently Asked Questions.
Get all your answers here and if something remains, feel free to contact us directly or book a strategy session.
We design and build agent-native custom software architectures from day one. Instead of simply building bolt-on API wrappers, we deploy multi-agent orchestration systems (like our Commander Architecture), run local secure LLMs to slash token expenses by 40–70%, and modernize legacy Microsoft ecosystem codebases to modern AI-native structures.
It is our proprietary 5-agent pipeline framework. High-tier cloud models (like Claude Opus) act as 'Supreme Commanders' to analyze complexity and structure task files, which are then processed at high concurrency by local models (like Qwen on Ollama) at around $0.001 per task, drastically lowering API costs.
By integrating custom prompt caching strategies and context-aware semantic routing, we achieve a prompt cache hit rate of ~90%. This bypasses redundant processing of duplicate context instructions to dramatically slash monthly token bills.
We specialize in modern high-performance tech stacks: Next.js/React, Drizzle ORM, SQLite/PostgreSQL databases, .NET Core 8 cloud services, React Native/Expo for mobile apps, and cognitive frameworks such as Semantic Kernel, FastAPI, and Neo4j Knowledge Graphs.
We implement secure architectures by deploying local LLMs inside your virtual private cloud (VPC), ensuring sensitive data never leaves your environment. We also establish strict end-to-end data encryption, audit trails, and role-based access control.
Yes, we specialize in converting legacy systems (WinForms, WPF, ASP.NET WebForms) to modern, distributed systems built on modern .NET 8, micro-frontend architectures, and containerized Docker services running in AWS/Azure.
A typical proof of concept (PoC) takes 2 to 4 weeks. Full enterprise agent orchestration systems or multi-agent swarms integrated with your legacy APIs take about 8 to 12 weeks to build, test, and deploy to production.
Absolutely. We build React Native applications using local SQLite databases (via Drizzle or WatermelonDB) that can perform complex tasks offline and sync changes securely with the cloud server once internet connectivity is restored.
Speculative decoding uses a small, fast model to suggest draft tokens, which are verified in parallel by a larger target model. This speeds up text generation by 2x to 3x and cuts down latency without losing output quality.
Yes. All custom code, agent system designs, proprietary database configurations, and custom integration scripts developed during our engagement are 100% owned by your company from day one.
Client Impact & Success
"SHIVAM ITCS completely transformed our content workflow. Their Commander Architecture cut our monthly LLM cost by 65% while keeping quality pristine."
Partner with SHIVAM ITCS to build resilient, scalable systems. Our senior engineering teams specialize in enterprise AI orchestration, legacy modernization, and high-performance cloud architecture.
Schedule a Technical Consultation →Get New Posts In Your Inbox
No spam. Deep technical content when we publish — roughly twice a month.