Build Smarter.
Ship Faster.AI Agent DevelopmentAI Agent DevelopmentMulti-Agent AI & SwarmsAdvanced Hybrid RAG EnginesLLM Cost OptimizationLegacy .NET ModernizationEnterprise SaaS Engineering
Deep technical content on agentic AI systems, LLM cost optimization, Commander Architecture, and production SaaS engineering — from 18+ years of building.
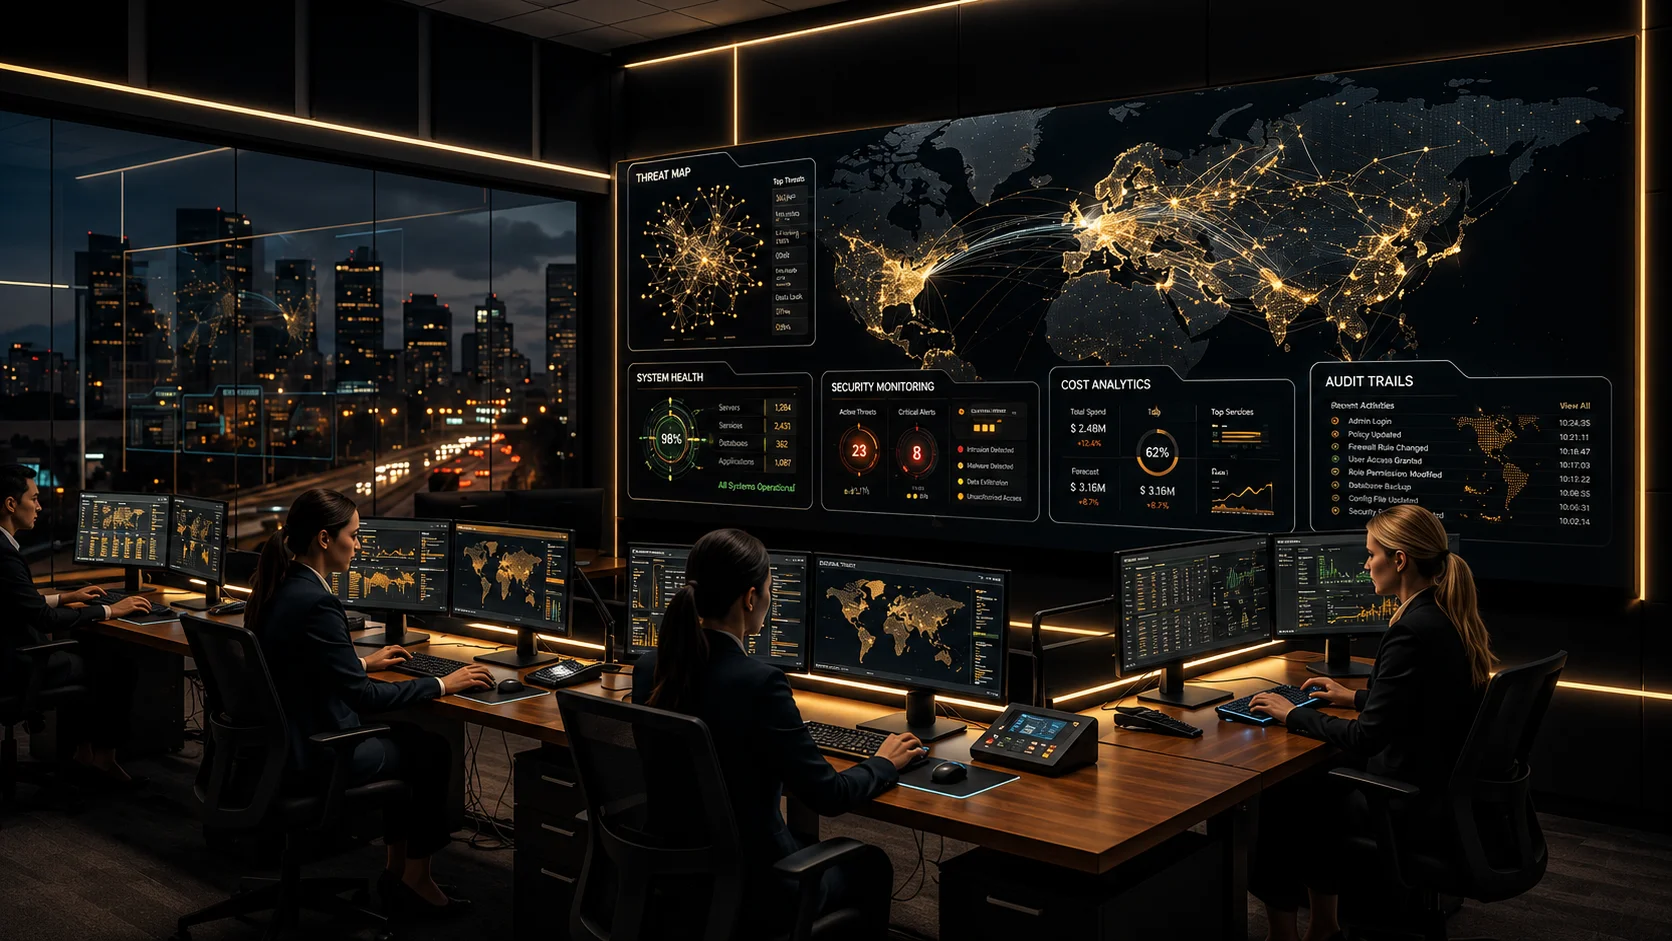
The Next Enterprise Gold Rush Is Not AI Models — It Is AI Governance
AI Governance: June 2026 Enterprise Intelligence Report
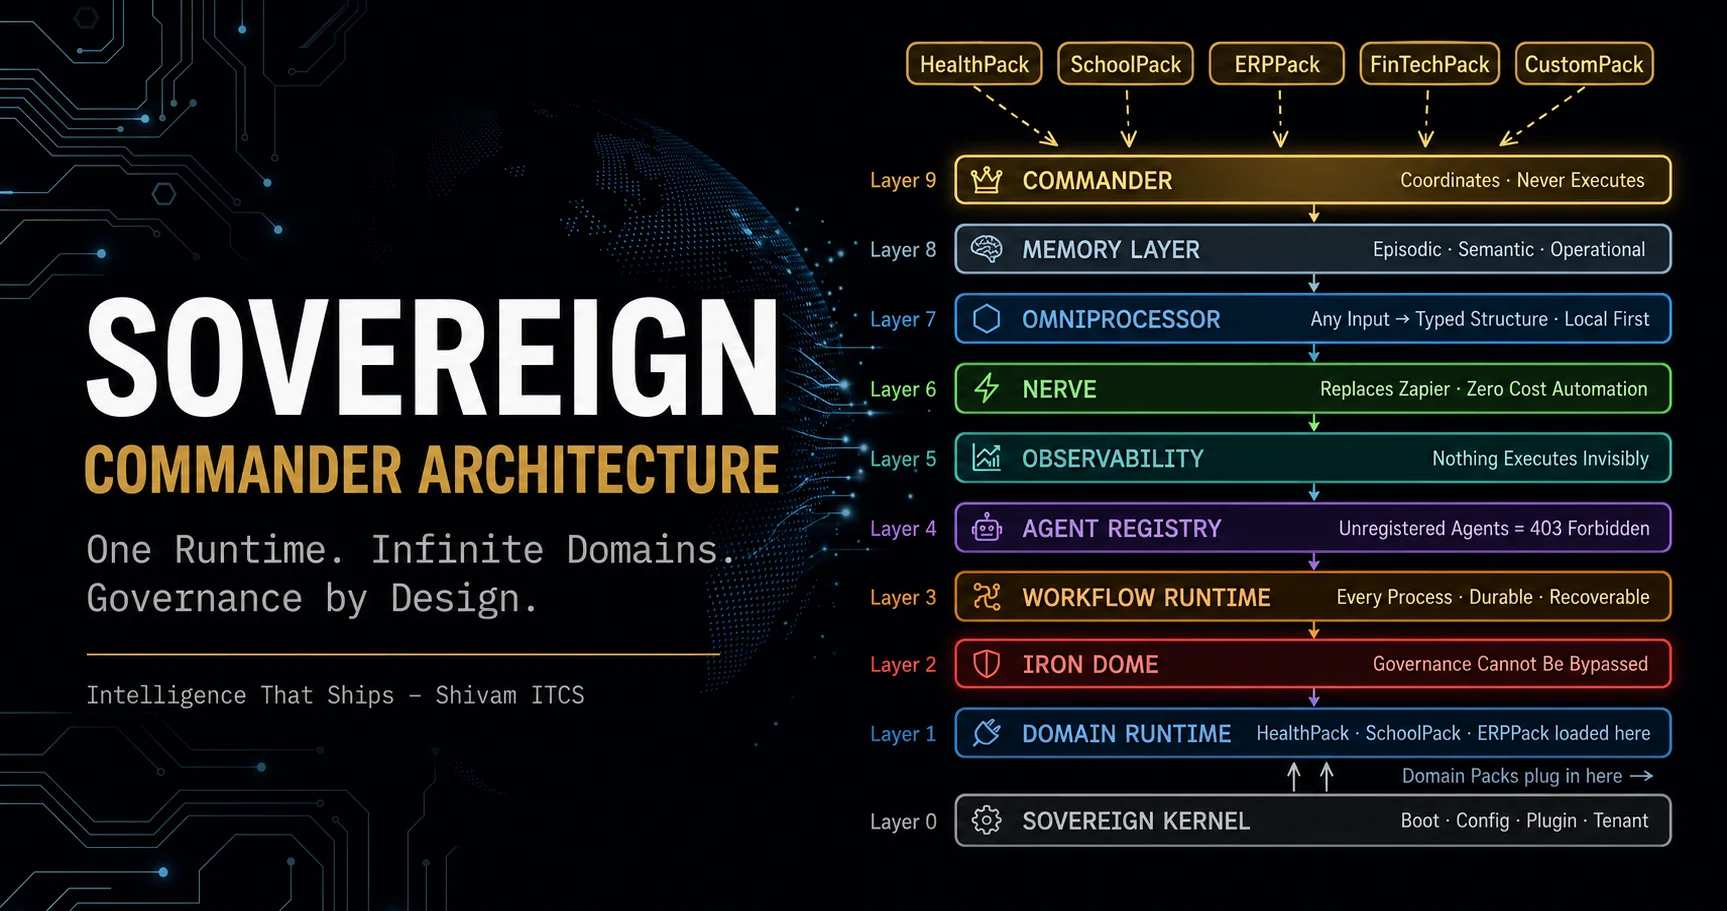
Commander Architecture: How We Cut AI Costs by 70% in Production
2 Jun 2026
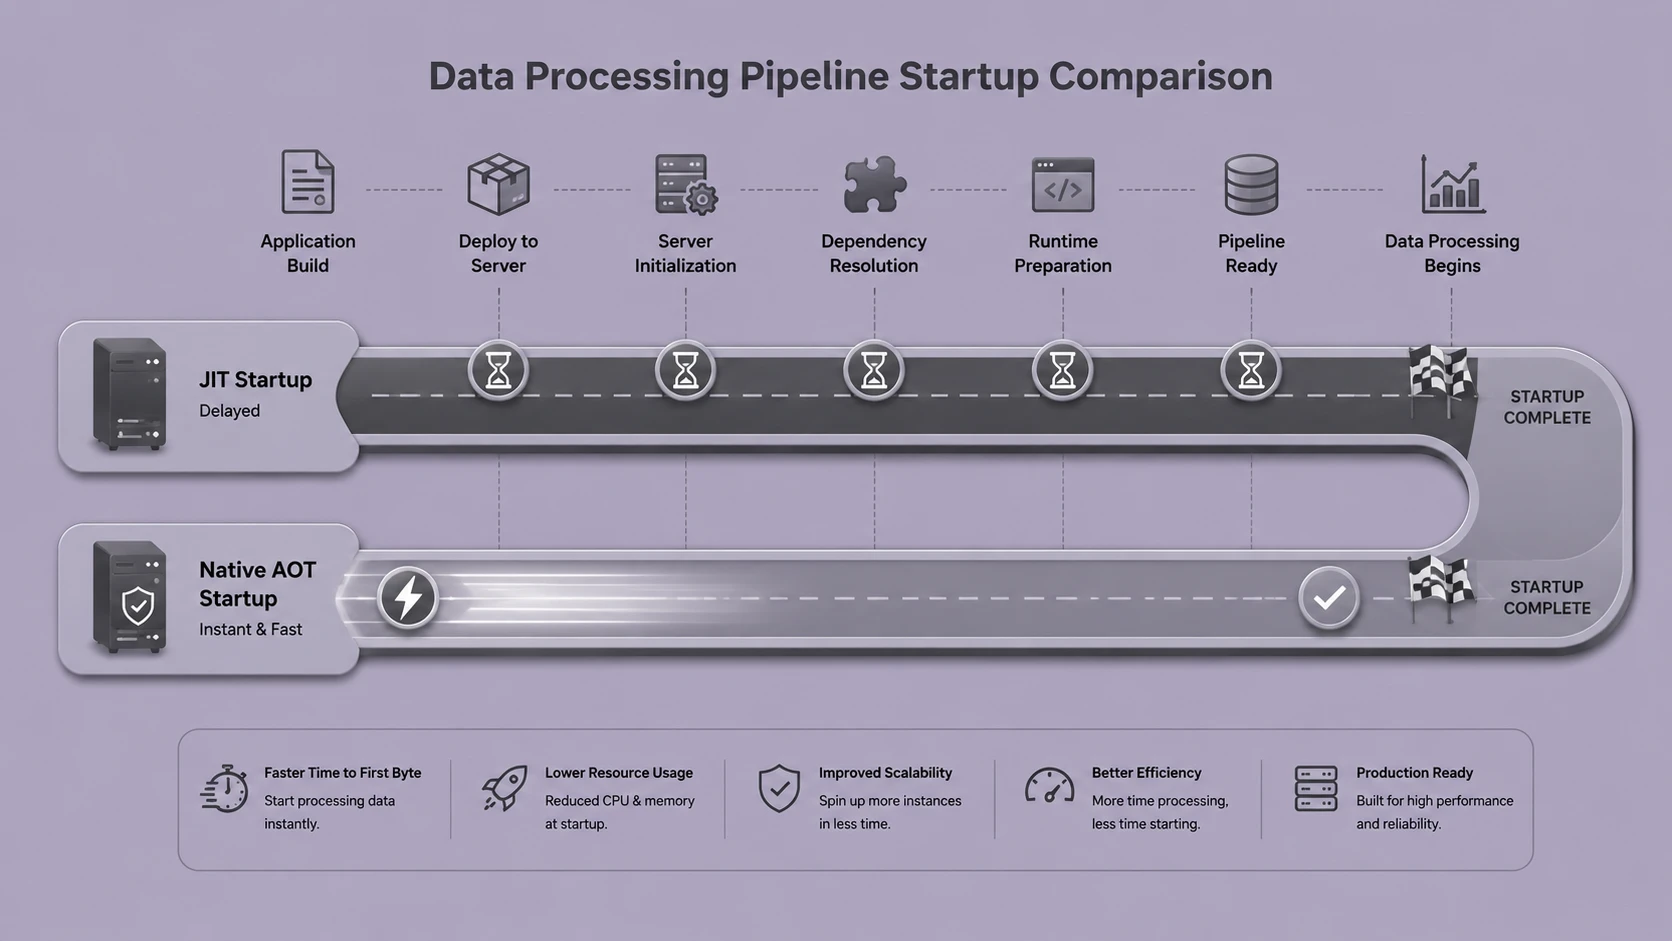
Native AOT in .NET 10: Reducing Server Cold Starts and Memory Footprint for AI Gateways
23 Apr 2026
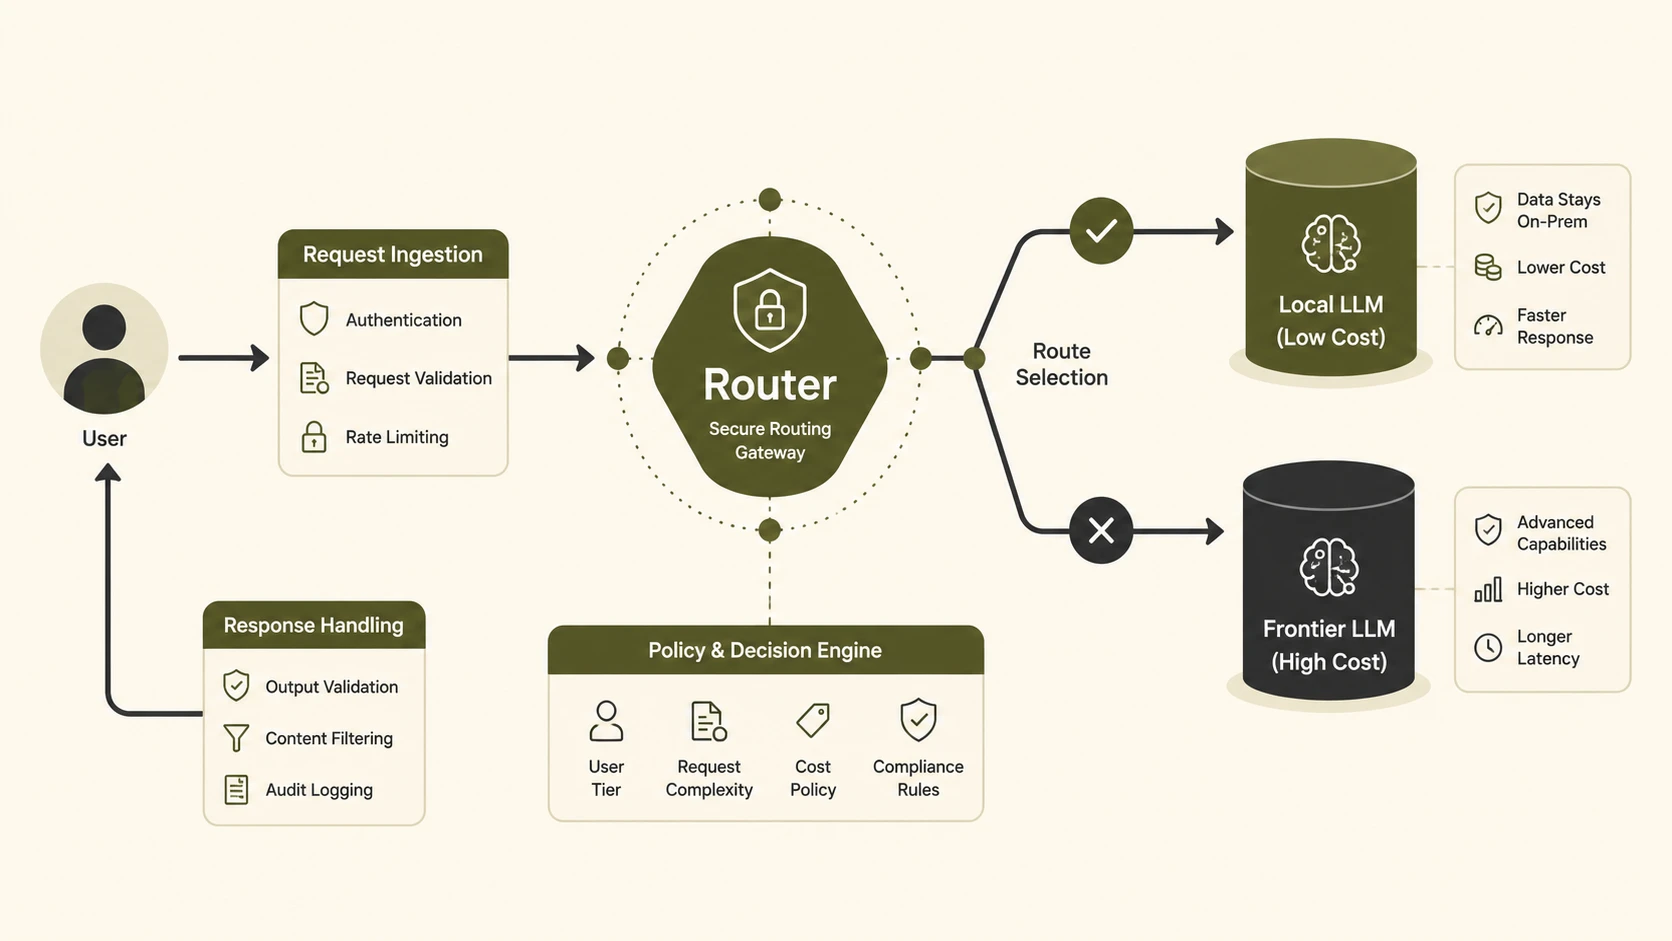
Cost-Optimized LLM Routing: Intelligently Dispatching Tasks Between Local and Cloud Models
26 Mar 2026
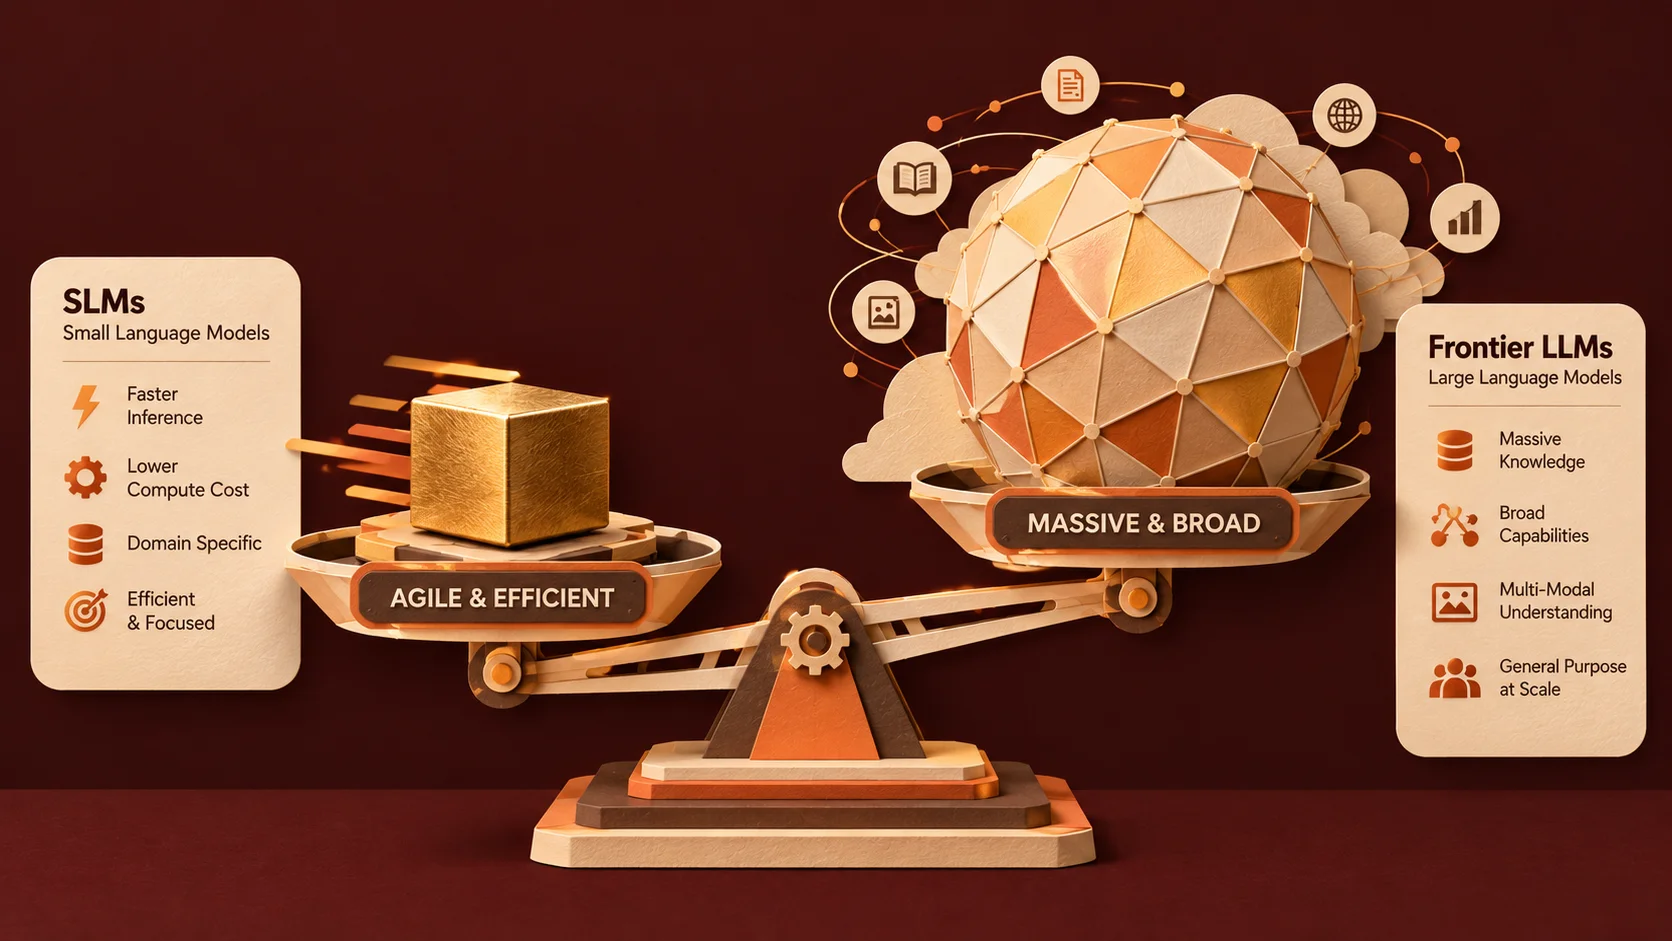
Small Language Models (SLMs) vs LLMs: When to Use What in 2026
Small Language Models are changing how enterprises design and deploy AI applications in 2026. While Large Language Models offer broad capabilities and advanced reasoning, SLMs can deliver faster, more cost-effective inference for focused tasks. This guide compares SLMs and LLMs across architecture, performance, infrastructure, security, and total cost of ownership. Learn when to use local models, when to choose a hosted LLM, and how to build hybrid AI systems that route each task to the most appropriate model.
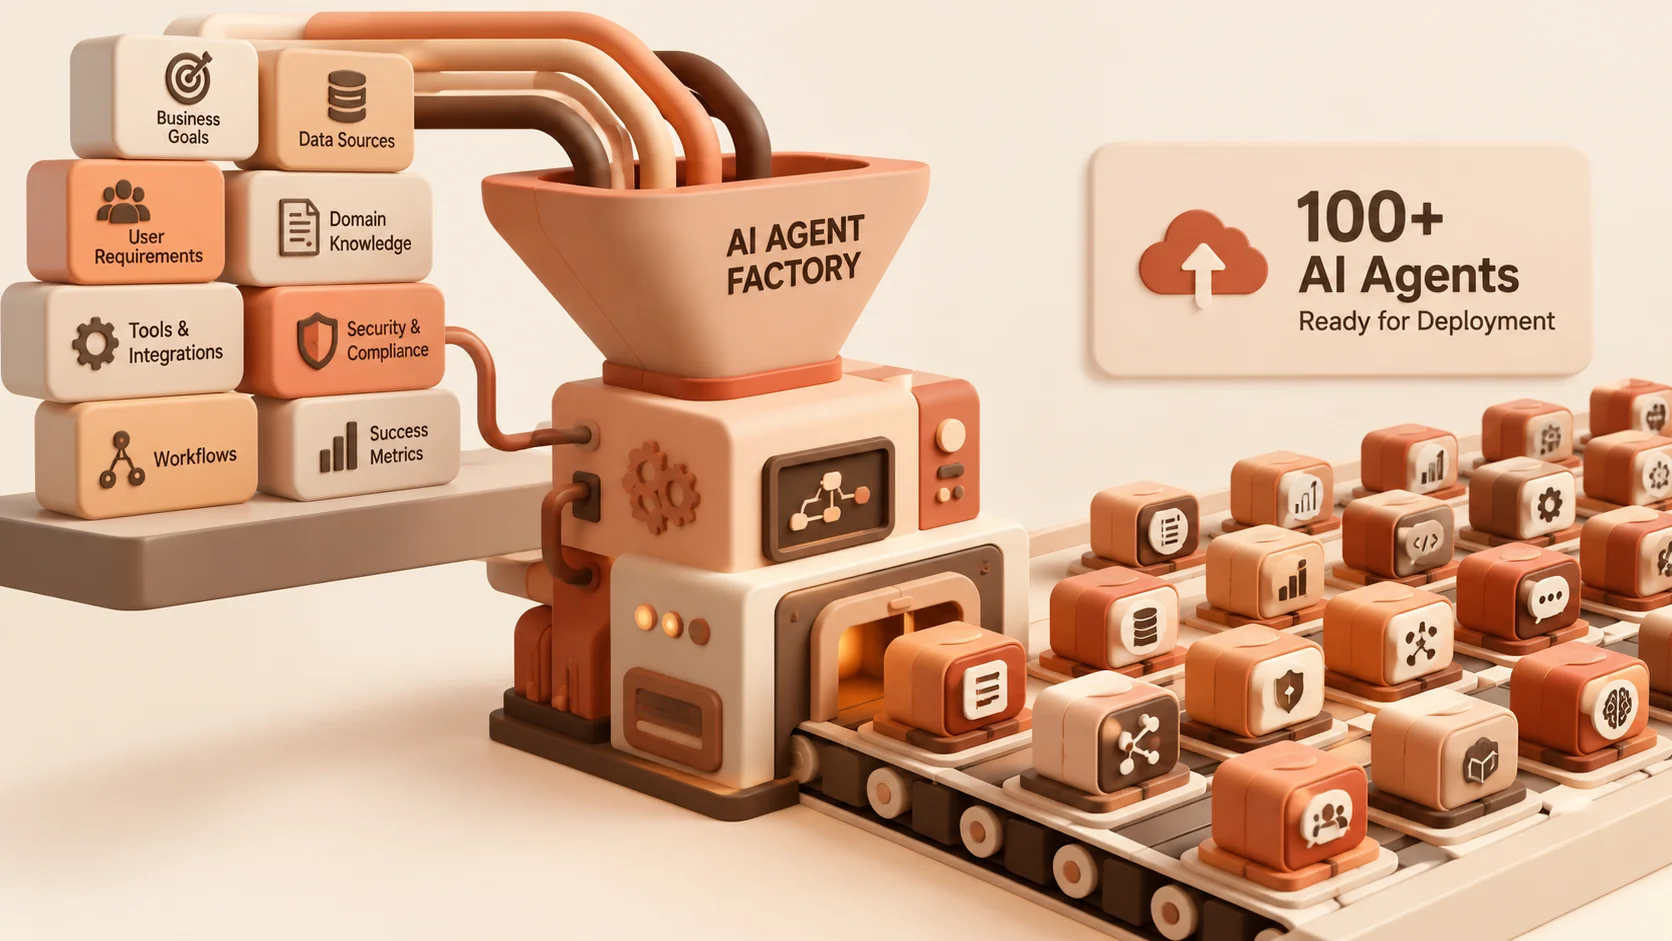
The Agent Factory: How to Build 100+ Specialized AI Agents at Scale
Building one AI agent is an engineering project. Building and operating 100 specialized agents is a platform engineering challenge. This guide explains how to design an Agent Factory that standardizes agent creation, dynamically routes requests, reuses tools and capabilities, enforces security policies, automates testing, and manages the full agent lifecycle. Learn how enterprise engineering teams can scale from isolated AI pilots to a governed ecosystem of specialized agents without creating 100 independent systems to maintain.
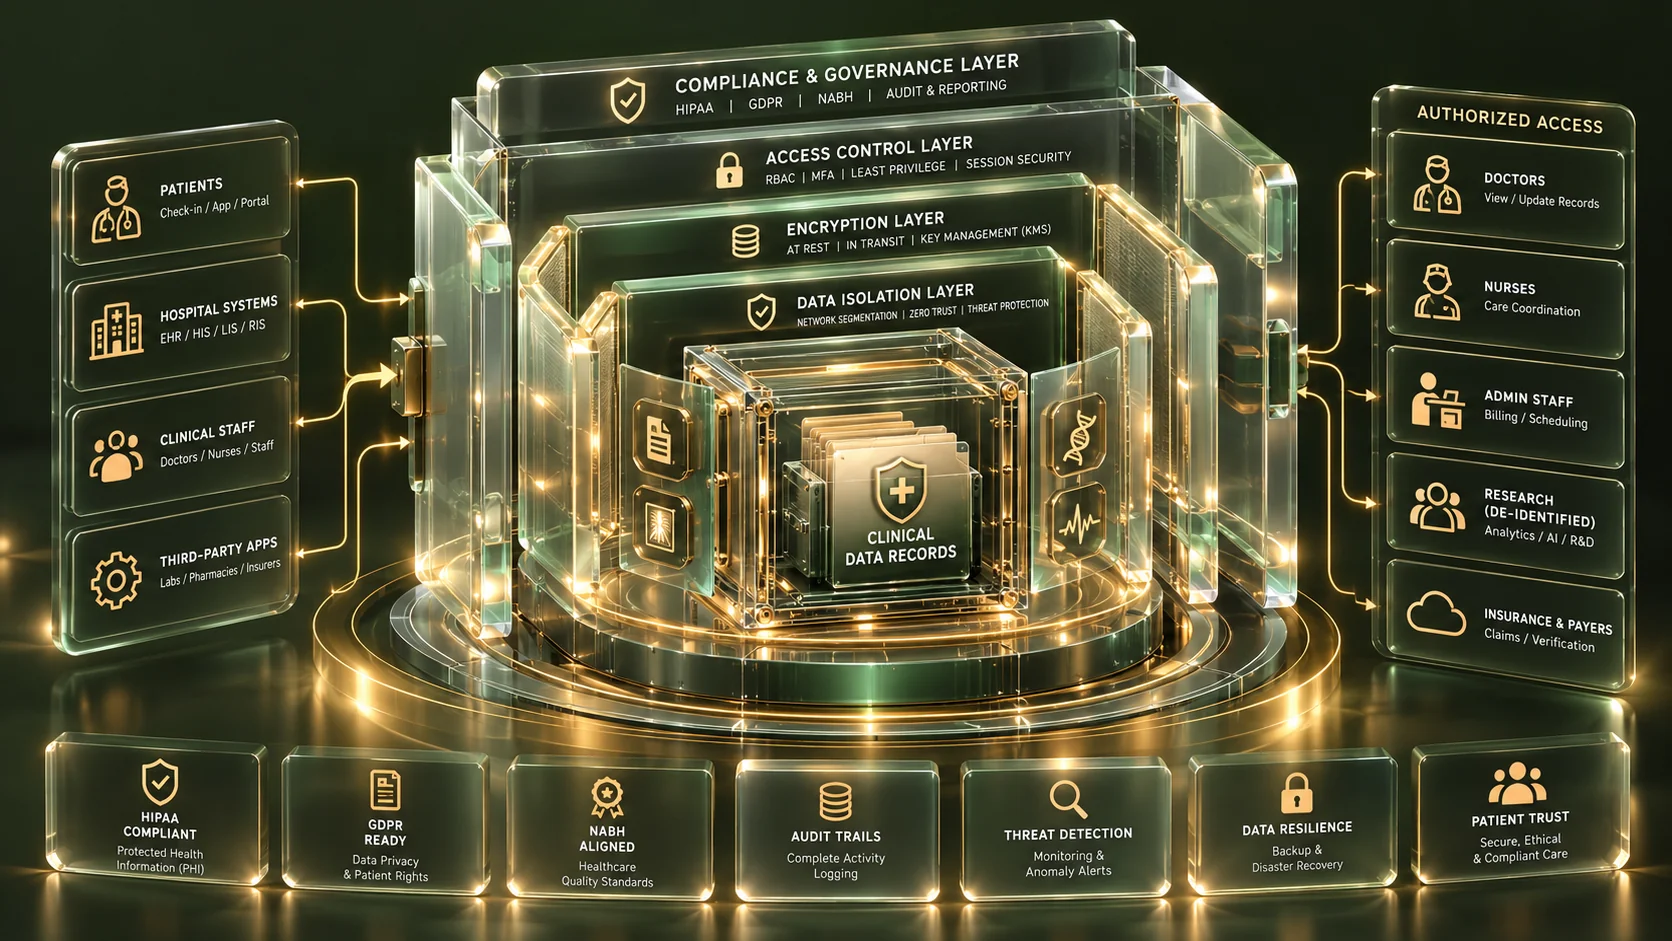
HIPAA-Compliant AI Agents: Governance Architecture for Healthcare
Healthcare AI agents introduce new governance challenges when they interact with electronic health records, clinical workflows, billing systems, and patient information. This technical guide explains how to design a HIPAA-aligned AI agent architecture using least-privilege access, business associate agreements, data minimization, encryption, immutable audit trails, prompt-injection defenses, human oversight, and continuous risk assessment. It also outlines a practical implementation strategy for healthcare organizations deploying agentic AI without compromising patient privacy or operational accountability.
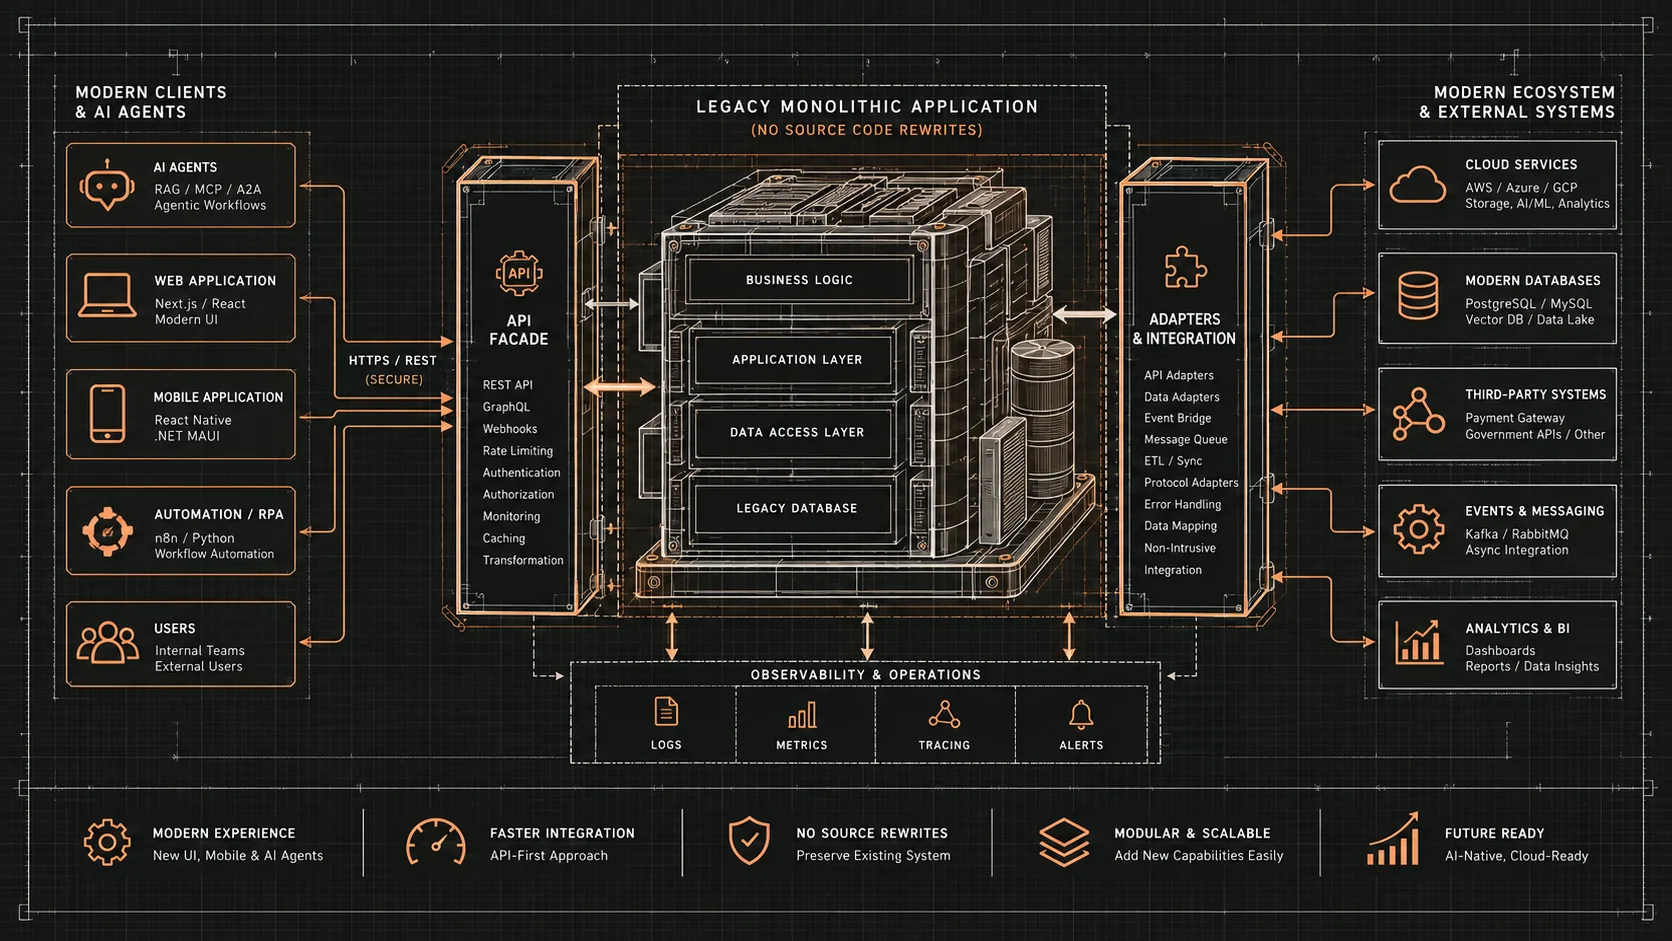
Legacy .NET to Agent-Native: A Zero-Rewrite Migration Playbook
Learn how to modernize legacy .NET applications for agentic AI without rewriting business-critical systems. This enterprise migration playbook explains facade adapters, ASP.NET Core reverse proxies, OpenAPI contracts, Semantic Kernel integration, agent orchestration, security boundaries, deployment strategies, and a phased roadmap for introducing AI capabilities while preserving existing business logic.
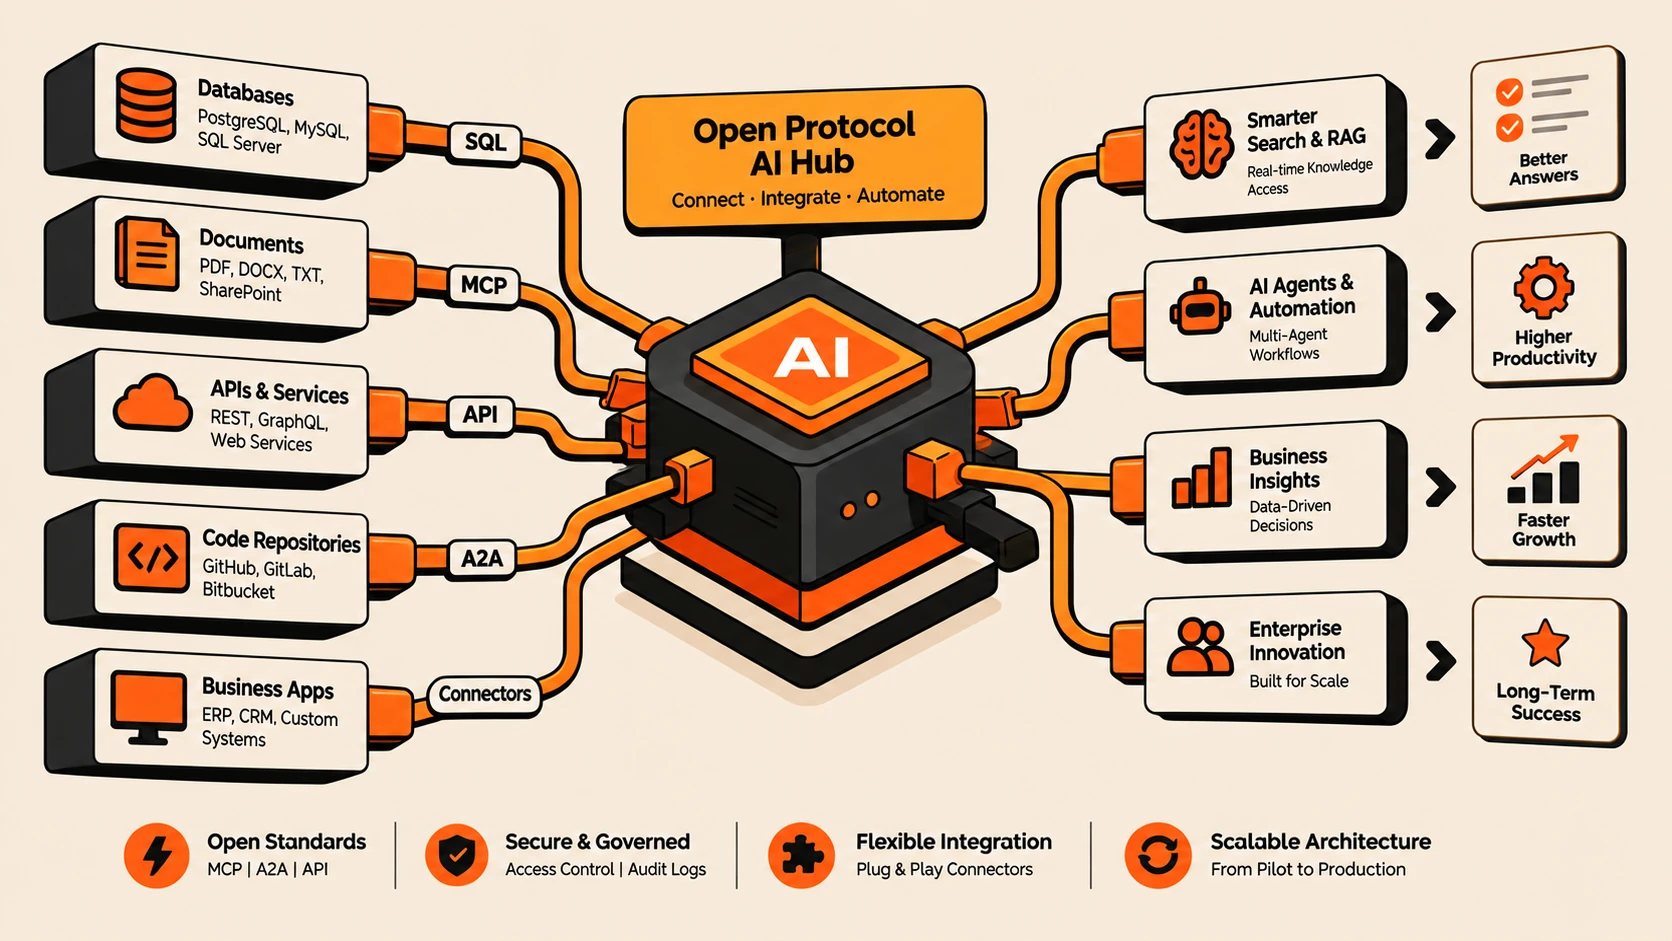
MCP Protocol Explained: Building the Agent Internet with Model Context Protocol
As enterprises move from isolated AI assistants to agentic systems, interoperability is becoming a critical challenge. Model Context Protocol (MCP) provides a standardized approach for connecting AI models with tools, data sources, enterprise applications, and other agents. This guide explains MCP architecture, enterprise adoption patterns, security considerations, and its role in building the emerging Agent Internet in 2026.
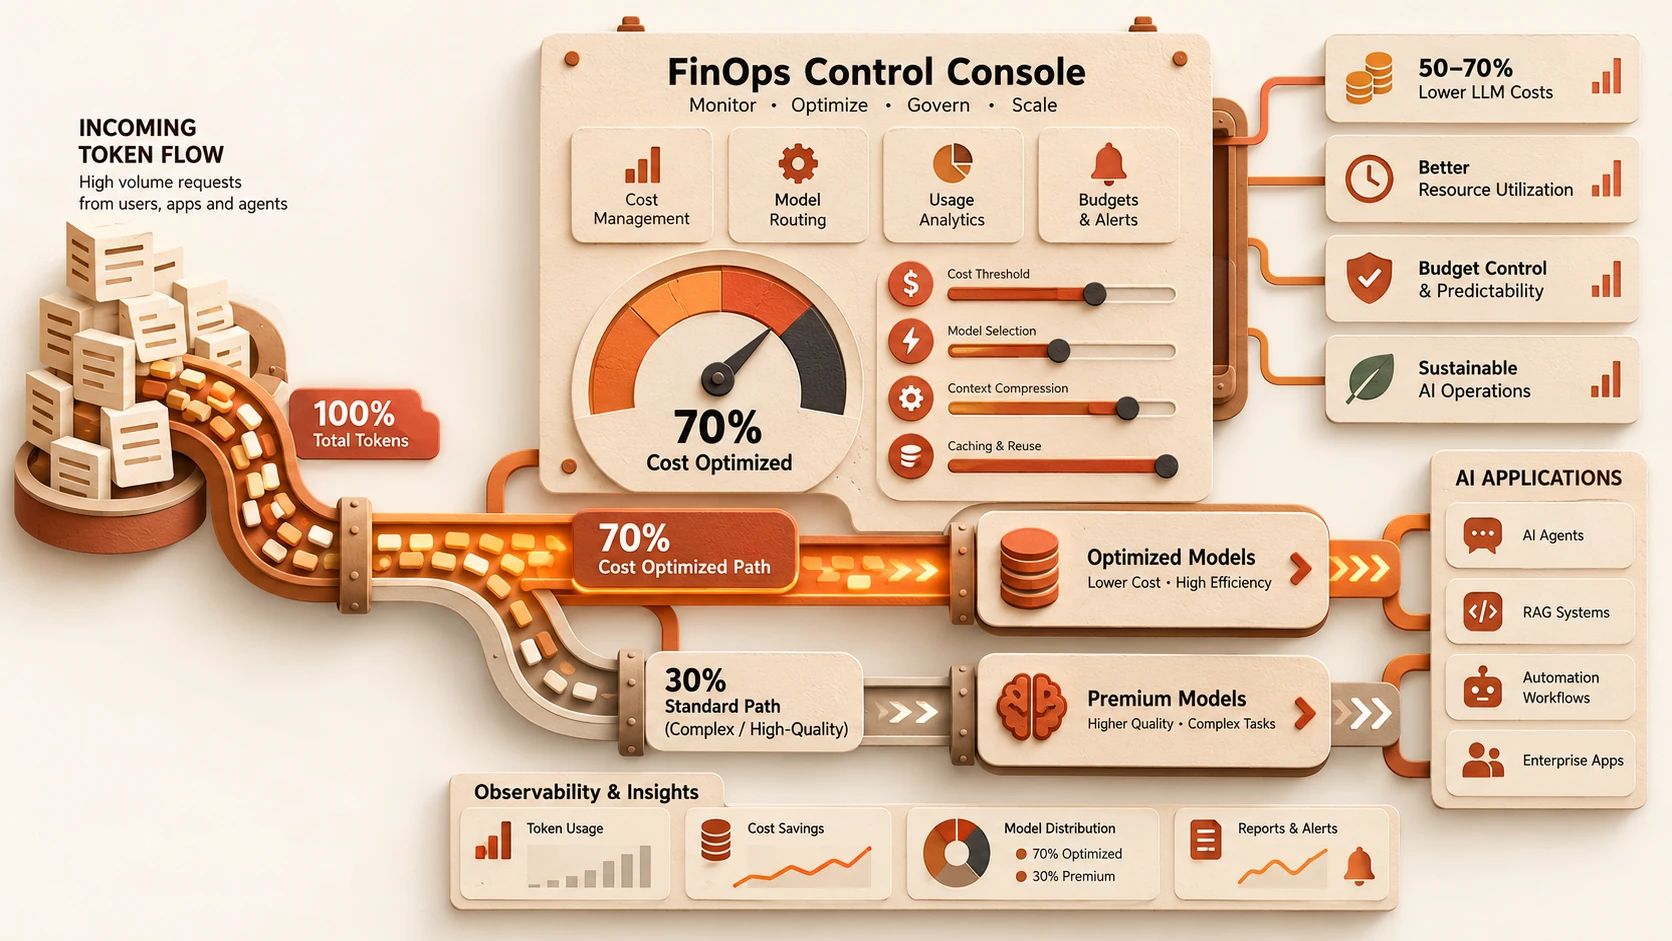
FinOps for AI: How We Cut LLM Costs by 70% Using Hybrid Routing
As enterprise AI adoption accelerates, inference spending is becoming a significant operational expense. This guide explains how a hybrid routing architecture can reduce LLM costs by up to 70% by matching workloads to the appropriate model, implementing governance controls, and applying FinOps principles to AI platforms.
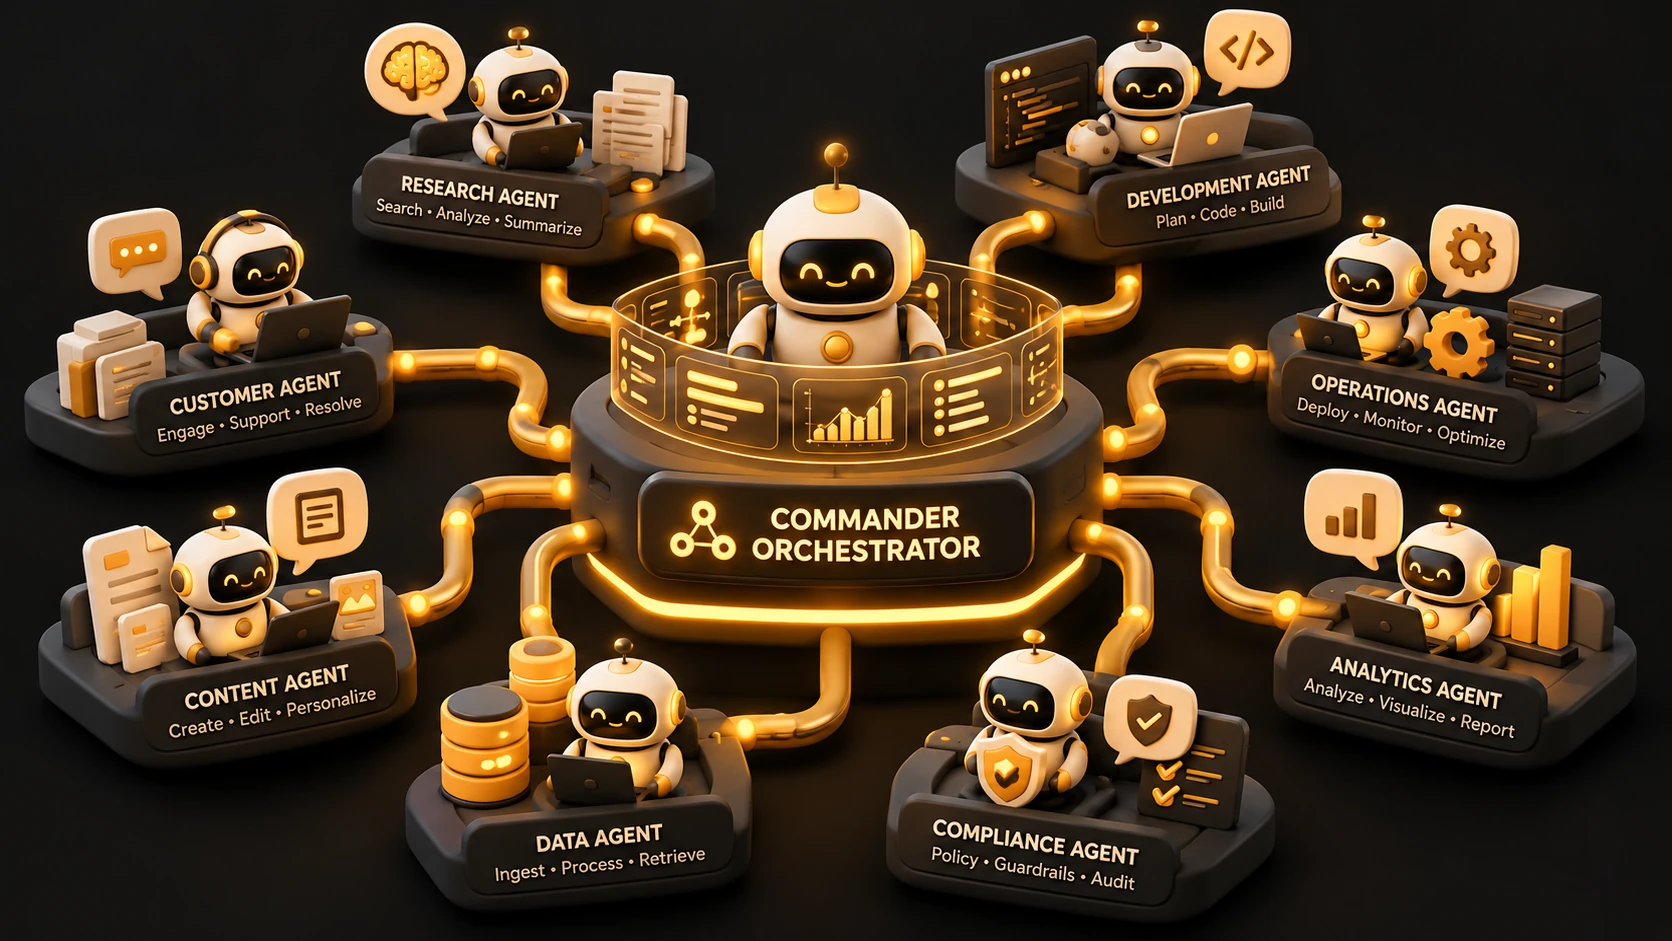
Multi-Agent Orchestration: The Microservices Moment for AI (2026 Guide)
Multi-agent orchestration is emerging as a foundational architectural pattern for enterprise AI systems. This guide explains how organizations are coordinating specialized AI agents, applying orchestration principles similar to microservices, and building scalable, secure, and governable AI platforms in 2026.
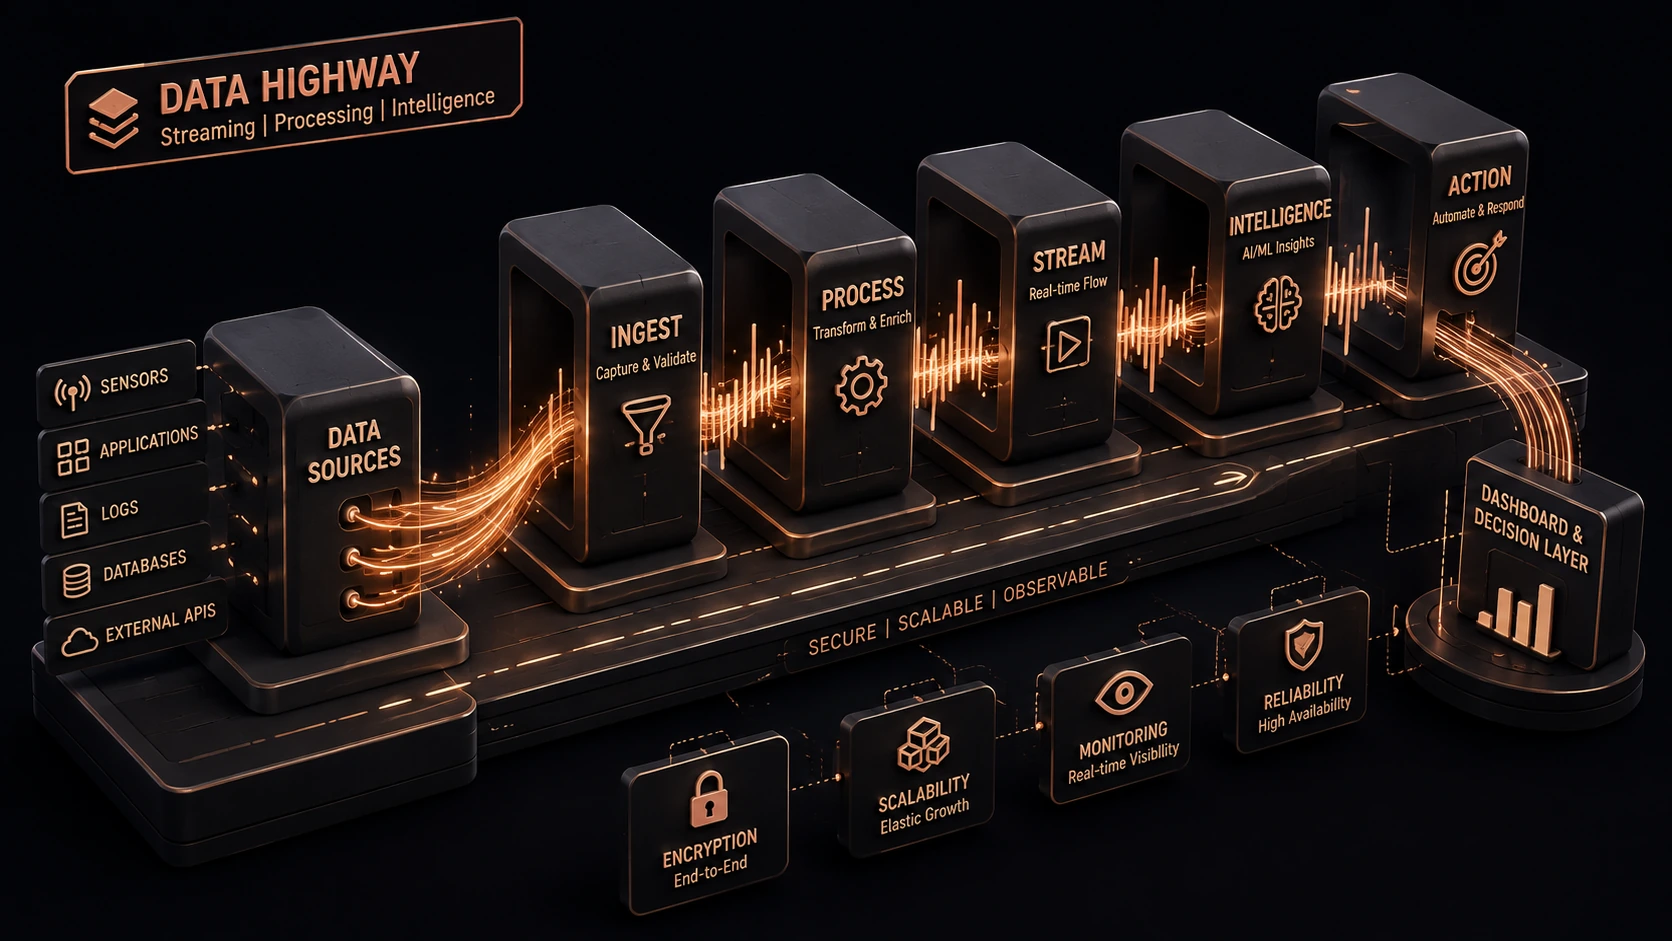
Voice AI Agents in 2026: Beyond Chatbots to Bidirectional Conversational Systems
Voice AI transforms traditional IVR systems into intelligent conversational agents that can listen, reason, execute workflows, and respond in real time. Using speech recognition, large language models, retrieval, memory, and speech synthesis, Voice AI powers customer service, sales, healthcare, and enterprise automation. This guide covers architecture, security, orchestration, latency, deployment, and production best practices.

The CIO's Guide to AI Agent Governance
A CIO's guide to establishing robust AI Agent Governance. Learn about audit trails, human-in-the-loop (HITL) systems, and compliance strategies for secure enterprise AI adoption.

Modernize Legacy .NET Applications with Agentic AI: Zero-Rewrite
Unlock the power of Agentic AI to modernize legacy .NET applications without a full rewrite. Learn architectural patterns, implementation steps, and best practices for enterprise success.

RAG with pgVector: Beyond LLM Hallucinations
Learn what RAG is and how pgVector, a PostgreSQL extension, revolutionizes LLMs by enabling efficient vector search for enterprise knowledge.

Local LLM Inference with Ollama and Qwen: An Enterprise Deployment Guide
Discover how enterprises can achieve secure, cost-effective Local LLM Inference using Ollama and Qwen. This guide covers architecture, implementation, and best practices.
Frequently Asked Questions.
Get all your answers here and if something remains, feel free to contact us directly or book a strategy session.
We design and build agent-native custom software architectures from day one. Instead of simply building bolt-on API wrappers, we deploy multi-agent orchestration systems (like our Commander Architecture), run local secure LLMs to slash token expenses by 40–70%, and modernize legacy Microsoft ecosystem codebases to modern AI-native structures.
It is our proprietary 5-agent pipeline framework. High-tier cloud models (like Claude Opus) act as 'Supreme Commanders' to analyze complexity and structure task files, which are then processed at high concurrency by local models (like Qwen on Ollama) at around $0.001 per task, drastically lowering API costs.
By integrating custom prompt caching strategies and context-aware semantic routing, we achieve a prompt cache hit rate of ~90%. This bypasses redundant processing of duplicate context instructions to dramatically slash monthly token bills.
We specialize in modern high-performance tech stacks: Next.js/React, Drizzle ORM, SQLite/PostgreSQL databases, .NET Core 8 cloud services, React Native/Expo for mobile apps, and cognitive frameworks such as Semantic Kernel, FastAPI, and Neo4j Knowledge Graphs.
We implement secure architectures by deploying local LLMs inside your virtual private cloud (VPC), ensuring sensitive data never leaves your environment. We also establish strict end-to-end data encryption, audit trails, and role-based access control.
Yes, we specialize in converting legacy systems (WinForms, WPF, ASP.NET WebForms) to modern, distributed systems built on modern .NET 8, micro-frontend architectures, and containerized Docker services running in AWS/Azure.
A typical proof of concept (PoC) takes 2 to 4 weeks. Full enterprise agent orchestration systems or multi-agent swarms integrated with your legacy APIs take about 8 to 12 weeks to build, test, and deploy to production.
Absolutely. We build React Native applications using local SQLite databases (via Drizzle or WatermelonDB) that can perform complex tasks offline and sync changes securely with the cloud server once internet connectivity is restored.
Speculative decoding uses a small, fast model to suggest draft tokens, which are verified in parallel by a larger target model. This speeds up text generation by 2x to 3x and cuts down latency without losing output quality.
Yes. All custom code, agent system designs, proprietary database configurations, and custom integration scripts developed during our engagement are 100% owned by your company from day one.
Client Impact & Success
"SHIVAM ITCS completely transformed our content workflow. Their Commander Architecture cut our monthly LLM cost by 65% while keeping quality pristine."
Partner with SHIVAM ITCS to build resilient, scalable systems. Our senior engineering teams specialize in enterprise AI orchestration, legacy modernization, and high-performance cloud architecture.
Schedule a Technical Consultation →Get New Posts In Your Inbox
No spam. Deep technical content when we publish — roughly twice a month.